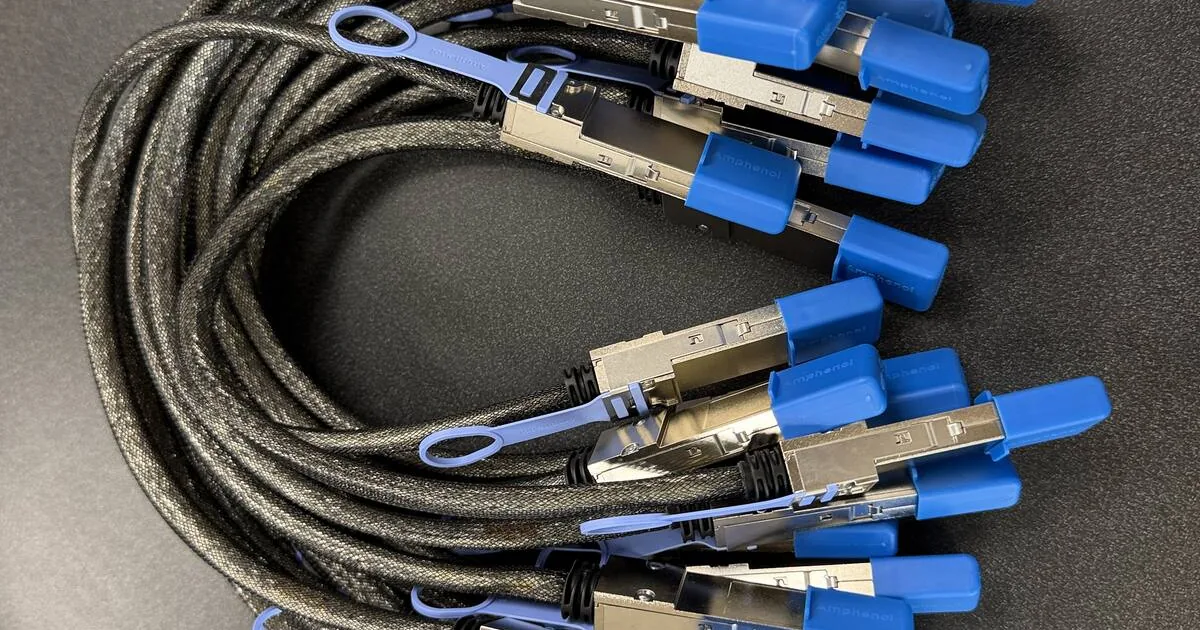
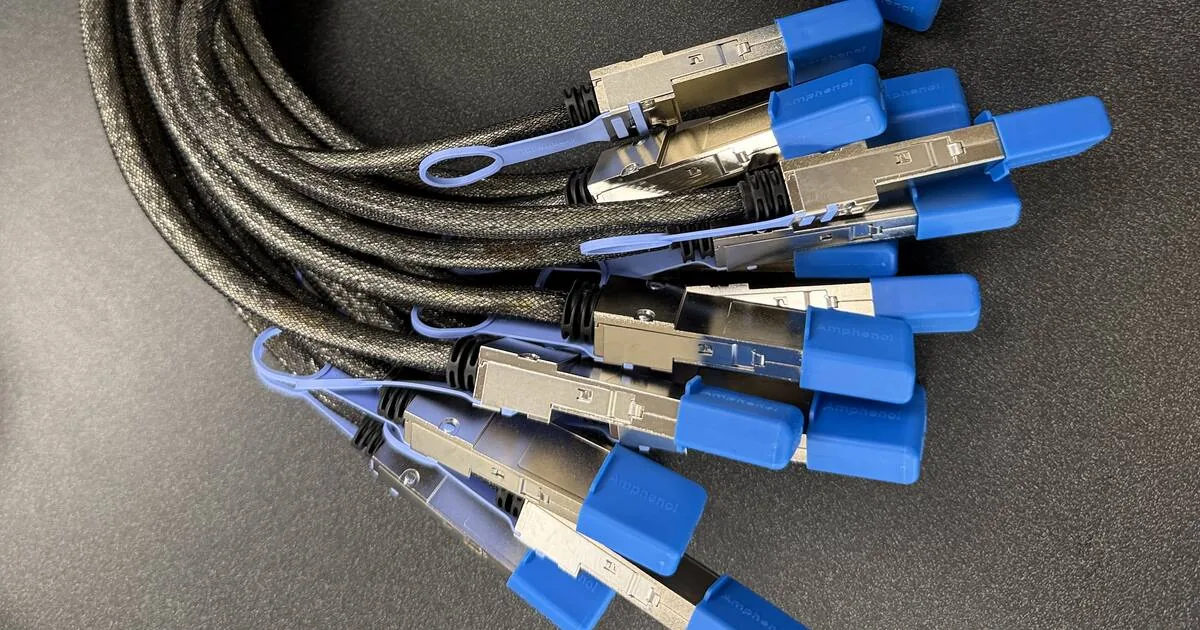
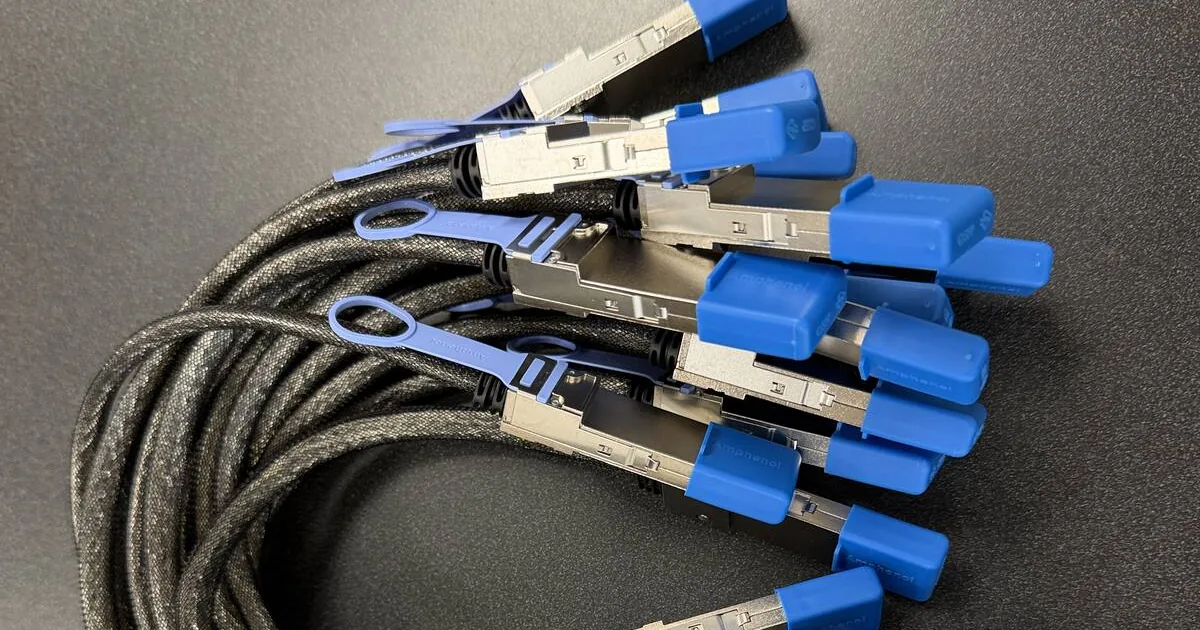
To connect two DGX Sparks you need exactly one cable: a 0.5 m QSFP112 400G passive direct-attach copper (DAC) cable, plugged into QSFP Port 0 on each unit. That is the whole shopping list, because every DGX Spark, and every other GB10 workstation, carries the same ConnectX-7 network controller with two QSFP112 ports, and NVIDIA's own "Connect Two Sparks" playbook joins the pair with a single direct QSFP cable. Petronella Technology Group, Inc. stocks that cable, the Amphenol NJAAKR-0006, for $159 with free US shipping, in stock and shipping in 1 to 3 business days.
The rest of this post is the detail behind that answer: what the port on the back of the box actually is, why a short passive cable is the right part and a longer or active one buys you nothing for two boxes on the same desk, which OEM GB10 systems take the identical cable, what a second cable between the same pair does and does not do, when three or more nodes change the picture, and the short bring-up checklist that proves the link is running at line rate before you load a model. Every measurement comes from our public GB10 cluster guide or from NVIDIA's documentation, linked where it is used.
Buy the DGX Spark cluster cable, $159 with free US shipping
The port on every GB10 box: two QSFP112 cages on a ConnectX-7
Turn a DGX Spark around and you will find, next to the RJ45 Ethernet jack, two identical square cages. Those are QSFP112 ports on an NVIDIA ConnectX-7 network controller, and NVIDIA's DGX Spark user guide documents each of them at up to 200 gigabits per second, Ethernet configuration only. The left port, the one closest to the RJ45 jack, is Port 0. The right port is Port 1. The same two cages, on the same ConnectX-7, are on the back of every GB10 workstation regardless of the badge on the front.
There is one structural fact about this port that explains almost everything else in this article. The ConnectX-7 connects to the GB10 chip over two independent PCIe Gen 5 x4 links, so each physical port shows up in Linux twice. Port 0 appears as two Ethernet interfaces, enp1s0f0np0 and enP2p1s0f0np0, and as two RDMA devices, rocep1s0f0 and roceP2p1s0f0. They are the same wire. Each PCIe half carries roughly 100 Gb/s, and to see the full 200 Gb/s on one cable you need traffic on both halves at once. NCCL does that on its own when you hand it both RDMA devices; a single TCP stream does not.
Our direct-cable measurements on two units, with the commands published in the guide's validation chapter, look like this:
- One PCIe half,
ib_write_bw: 111.86 Gb/s. - Both halves running concurrently: 98.04 + 98.04 = 196.08 Gb/s, about 98 percent of the 200 Gb/s line rate.
So one cable, correctly configured, delivers about 196 Gb/s, which is roughly 25 GB/s. Hold on to that number, because it is the reason a second cable does not help and the reason a second Spark is a capacity decision rather than a speed decision.
Why a 0.5 m passive DAC is the right part to connect two DGX Sparks
NVIDIA's user guide lists the approved cables for the DGX Spark QSFP ports: the Amphenol NJAAKK-N911 (QSFP to QSFP112, 32 AWG, 400 mm, LSZH), the Amphenol NJAAKK0006 (the 0.5 m version of the same part), and the Luxshare LMTQF022-SD-R (a QSFP112 400G DAC, 400 mm, 30 AWG). All three are short passive QSFP112 direct-attach copper cables rated for 400G. The cable Petronella Technology Group, Inc. stocks is the Amphenol NJAAKR-0006, a 0.5 m QSFP112 passive DAC at 30 AWG from the same Amphenol family, built to that NJAAKK0006 / LMTQF022-SD-R specification. It is not the same part number as NVIDIA's listed cables, and we do not claim it is; it is the 0.5 m length built to the same spec, and owners on the NVIDIA developer forum report full-rate links with it.
Three properties make this the right part, and they are worth understanding rather than memorizing:
- Passive. A passive DAC is a copper cable with a QSFP connector at each end and no electronics in the plug. Nothing to power, nothing to update, no vendor firmware lock. The ConnectX-7 drives it directly.
- QSFP112. This is the form factor the port and NVIDIA's documentation call for. The GB10 negotiates its node-to-node link at 200 Gb/s, which is why buyers on the NVIDIA developer forum keep asking whether a 200G QSFP56 cable would do. Some report that it links. For a pair of workstations at this price, buy the cable NVIDIA documents; a QSFP112 400G DAC is guaranteed against the spec the Spark Stacking guide names and removes the one variable you would otherwise be debugging.
- 400G rating, 200G link. The label says 400G because that is what the cable can carry. The GB10's ConnectX-7 port is documented at up to 200 Gb/s, so that is where the link negotiates. The extra rating is headroom, not speed you get. Our explainer on DGX Spark bandwidth and what 400G really means walks through the bits-versus-bytes arithmetic.
Practically, the 0.5 m length is the one that fits how two Sparks actually sit: side by side on a desk or stacked one on the other. A DGX Spark is a small box, and 0.5 m of cable reaches from the back of one to the back of the other with slack to spare in either arrangement.
Why you do not need a longer or an active cable for two boxes side by side
Longer cables exist and they have their place. In our guide's hardware chapter we lay out the rule of thumb: 0.5 m covers side-by-side or stacked units; if a monitor separates them you want 1 m; across two shelves, 2 m; across a small rack, 3 m, and at that length you are into active copper. None of that applies to the question in the title. Two DGX Sparks on one desk are a 0.5 m job.
There are two reasons not to reach for a longer or active cable "just in case":
- An active cable, or an optical transceiver pair, adds powered electronics to a link that a passive DAC handles at full rate over half a meter. You add cost and a failure point and gain no bandwidth, because the port tops out at 200 Gb/s whatever the medium.
- Excess passive copper is dead weight behind the machines. A 0.5 m DAC is the length NVIDIA's own listed parts come in (400 mm and 0.5 m), which tells you the length the design assumed.
If your two units genuinely will not sit within half a meter of each other, choose the length for the distance. But if they are on the same desk, the short passive cable is not a compromise. It is the correct part.
Which GB10 boxes take the same cable
Every GB10 workstation ships the same NVIDIA GB10 Grace Blackwell system-on-chip, the same 128 GB of unified memory, and the same ConnectX-7 with two QSFP112 ports. The cable is identical across all of them, and brands can be mixed in one cluster. In our lab we run MSI units and DGX Spark Founders Edition units on the same switched fabric, and a DGX Spark pair and an MSI pair measured within 0.1 Gb/s of each other. We keep a fit-notes page for each chassis:
- NVIDIA DGX Spark (Founders Edition): the DGX Spark cluster cable hub page.
- Dell Pro Max with GB10 cluster cable
- ASUS Ascent GX10 cluster cable
- HP ZGX Nano cluster cable
- Lenovo ThinkStation PGX cluster cable
- MSI EdgeXpert cluster cable
- Gigabyte AI TOP ATOM cluster cable
- Acer Veriton GN100 cluster cable
The only practical difference we have hit between vendors is the network configuration system: the DGX Spark Founders Edition ships with netplan (systemd-networkd), and the MSI EdgeXpert ships with NetworkManager. The cable, the port, the link rate and the validation commands are the same. A DGX Spark connected to a Dell Pro Max GB10, or an ASUS GX10 connected to a Lenovo PGX, uses this one cable and behaves like any other pair.
What a second cable between the same pair does not do
This is the most common follow-up question, and the answer surprises people: a second cable between the same two units does not add bandwidth to the link you already have. Each QSFP112 cage is one port, and one port is one 200 Gb/s link. The "extra" capacity people are hoping to unlock is already inside the first cable, in the two PCIe halves described above. What you need for the full 196 Gb/s is both halves configured, meaning two interfaces and two addresses on each end, not two cables.
Plugging a second cable from Port 1 to Port 1 creates a second, separate 200 Gb/s link between the same two machines. Software that knows about both links can use both, but it also consumes the only other port on each unit, which is exactly the port you need if a third node ever joins. For two nodes, one cable is the documented and the sensible configuration. If you bought a 2-pack, the second cable is a spare or the start of a second pair, not a speed upgrade for the first.
The same logic explains why bonding the two Linux interfaces of one port does not do what people expect. RDMA traffic, which is what NCCL and the serving stacks actually use, bypasses the bond and talks to the RDMA devices directly. A single TCP stream on the GB10's ARM cores sits near 12 Gb/s no matter how the interfaces are arranged. And a bond is the one thing that can hold a stale address and a live route after a cable is moved. Two plain interfaces with two plain addresses have no such failure mode.
Three nodes is a ring, four or more is a switch
Two ports per unit sets the ceiling for direct cabling. NVIDIA documents direct connections for up to three systems and a switch for four:
- Two nodes: one cable, Port 0 to Port 0. This article.
- Three nodes: a ring of three cables, each unit using both ports, and every cable joining a Port 0 to a Port 1. That port mapping matters because NVIDIA's ring playbook puts the matching subnet on each Port 0 / Port 1 pair; wire Port 0 to Port 0 and every link lights up but ping fails. Our port-by-port wiring guide for a three-Spark ring covers it, and the 3-pack ring kit is the three cables it needs.
- Four or more nodes: a switch. With two ports each, four units wired as four point-to-point links leave two of them with no direct path to each other; we built exactly that before buying a switch and confirmed there was no route between the non-adjacent pair. Our four-node switch-versus-ring post has the parts list, and the two-Sparks-to-switched-fabric write-up shows the whole progression.
The single cable in this post is the first step of every one of those builds. If you are buying for two today and think a third is likely, the 3-pack ring kit at $435 is the three cables a ring needs, and the topology change later is three cables and an hour, not a new set of parts.
Bring-up checklist after you connect two DGX Sparks
NVIDIA's "Connect Two Sparks" playbook rates the job at about one hour including validation, medium risk because it reconfigures the network, and reversible by removing the netplan configuration. Its prerequisites are two systems, SSH access to both, root or sudo on both, the same username on both, and key-based SSH between them with no interactive prompt. NVIDIA also ships a discover-sparks.sh script for discovery and key distribution and a Sync Cluster Assistant that automates discovery, validation and SSH setup. Whichever route you take, these are the checks that prove the link is real, in the order that rules out one fault before the next test can misreport it:
- Link speed and state. On each unit,
ethtool enp1s0f0np0 | grep -E 'Speed|Link'should report 200000Mb/s and Link detected: yes, on both halves of the port. This proves the cable and the NIC negotiated. It does not prove throughput. - One subnet per link, per half. Give the first half of the link its own subnet and the second half a different one, on both ends. A point-to-point /30 per half works for two nodes; a flat /24 per half is what we run on the switch and is simpler to reason about even for a pair. Addresses that live only in the running kernel do not survive a reboot: on a DGX Spark put them in a netplan file, on an MSI in NetworkManager profiles.
- No default route on the fabric. Neither fabric interface should ever own a default route. Set the NetworkManager profile to never-default, or leave gateways out of the netplan file, and audit with
ip routeafter every change. Every fabric route should point at a fabric interface with carrier, and a carrier-down interface must not still hold an address. - MTU 9000, end to end. Set
mtu 9000on every fabric interface on both units. There is no negotiation to save you: a 1500-byte interface on one end silently fragments or drops large frames and NCCL bootstraps then stalls. Verify with a jumbo ping that forbids fragmentation,ping -M do -s 8972 <peer>, on both halves. 8972 is 9000 minus the IP and ICMP headers. - RDMA bandwidth, one half at a time and then both. Run
ib_write_bwfrom the perftest package against one RDMA device, then run two pairs concurrently, one per half, and add the results. Expect about 111 Gb/s per half and about 196 Gb/s with both running. This is the only test that catches a power-throttled NIC. - If a half reads 12 to 13 Gb/s with everything else green, update the OS and firmware and reboot before doing anything else. One of our units showed 200G, RS-FEC, PCIe Gen5 x4 and a clean status while delivering 12.74 Gb/s; a full OS upgrade took it to 111.86. Owners on the NVIDIA developer forum also report that a freshly plugged DAC can run far below line rate until the unit is fully powered off and unplugged from the wall for about a minute.
The full command set, the GID index lookup for RoCE v2, and the six-node validation matrix are in the guide's validation chapter. For two nodes the six steps above are enough.
What buyers get wrong
The cable questions that reach us by phone and email cluster around the same few mistakes, and each one costs either money or hours. In rough order of frequency:
- Buying two cables for two boxes. One cable is the full link. The second port is for a third node. See the section above.
- Measuring the link with a single iperf3 stream. A single TCP stream on the GB10 sits near 12 Gb/s regardless of the cable. That number is a CPU benchmark, not a fabric measurement. Use
ib_write_bwas the authority. - Configuring one half of the port. If you set up
enp1s0f0np0and forgetenP2p1s0f0np0, you will measure about 111 Gb/s and wonder where the other half went. Both halves need an interface, an address and a route. - Expecting a faster model. Linking two units pools memory so a model that does not fit in 128 GB can load, and it lets a workload span two GPUs. It is a capacity play. Decode on a single GB10 is bound by its 273 GB/s memory bus, and a 25 GB/s link cannot change that. The guide's numbers: a single unit runs models up to roughly 200B parameters, two linked units up to 405B.
- Sharding over the wrong network. We measured the same dense 27B FP8 model at 1,963 tokens per second prefill and 8.3 decode on one unit, and 539 and 3.5 across four units in tensor parallel over ordinary 10 Gb/s Ethernet. Extra nodes over the management LAN made it slower. Tensor parallel is only worth running over the RDMA fabric at line rate.
- Trusting a green status page. Link up, 200G, no errors, and 12.74 Gb/s of actual throughput happened to us. Re-measure after any rebuild, any driver update and any cable move.
- Adding a fourth node to a ring. Three is the switchless ceiling. Four or more is a switch.
What two Sparks buy you, honestly
A second GB10 is worth buying for the right reason. The GB10's 128 GB of unified memory delivers 273 GB/s. The link between two units delivers about 25 GB/s before protocol overhead, so local memory is roughly eleven times faster than the fastest path to the next node. That ratio means clustering is a capacity move first: two units hold a model that one cannot, and for memory-bound inference and fine-tuning of larger models that is exactly the win you want. Where tensor parallel across the fabric does add per-stream speed is on mixture-of-experts models whose per-rank working set shrinks. Where it does not is a dense model that already fits in one box.
Once the fabric is at line rate it is rarely the limiter. During a two-node run in our lab, 11 GB crossed the RDMA device over the whole job; that is collective traffic, not a bottleneck. When the fabric is not at line rate, because of a throttled NIC or a path that fell back to the management LAN, it becomes the only thing that matters, which is why the checklist above exists. For measured single-node and multi-node figures across the GB10 family and the larger NVIDIA systems, see our LLM benchmarks page.
Frequently asked questions
What cable do I need to connect two DGX Sparks?
One 0.5 m QSFP112 400G passive direct-attach copper cable, QSFP Port 0 to QSFP Port 0. Petronella Technology Group, Inc. stocks the Amphenol NJAAKR-0006, a 0.5 m 30 AWG QSFP112 passive DAC built to the NVIDIA-approved specification, for $159 with free US shipping, in stock and shipping in 1 to 3 business days.
Do I need one cable or two to connect two DGX Sparks?
One. A single cable is the full 200 Gb/s link; we measure about 196 Gb/s with both PCIe halves of the port configured. A second cable between the same two units is a second link, not a faster one, and it uses the port you would need for a third node.
Which port do I plug the cable into?
Port 0 on each unit, the QSFP port closest to the RJ45 Ethernet jack. For two nodes the choice does not affect bandwidth; it keeps the interface names consistent with NVIDIA's playbook. In a three-node ring every cable must join a Port 0 to a Port 1.
The cable says 400G. Do I get 400G between two Sparks?
No. NVIDIA documents each ConnectX-7 port on the GB10 at up to 200 Gb/s, and the cable negotiates at 200G. The 400G rating is the cable's capability and buys headroom, not speed.
Does the same cable work on a Dell, ASUS, HP, Lenovo, MSI, Gigabyte or Acer GB10 workstation?
Yes. Every GB10 system uses the same ConnectX-7 with the same two QSFP112 ports, so the cable is identical across the DGX Spark, Dell Pro Max GB10, ASUS Ascent GX10, HP ZGX Nano, Lenovo ThinkStation PGX, MSI EdgeXpert, Gigabyte AI TOP ATOM and Acer Veriton GN100. Brands can be mixed in one cluster.
Can I use a longer cable to connect two DGX Sparks?
You can, but two units on the same desk do not need one. The 0.5 m passive DAC covers side-by-side and stacked units. Choose 1 m if a monitor separates them, 2 m across two shelves, and 3 m active copper across a small rack. A longer or active cable adds no bandwidth.
Will connecting two DGX Sparks make my model faster?
Usually not for a model that already fits in one unit. Clustering is a capacity play: a single GB10 runs models up to roughly 200B parameters and two linked units run up to 405B. Decode is bound by the 273 GB/s memory bus, which the 25 GB/s link cannot change. Mixture-of-experts models can gain per-stream speed with tensor parallel across the fabric.
How many DGX Sparks can I connect without a switch?
Three. Two units use one cable; three units use three cables in a ring, each unit using both ports. Four or more units need a 200G-class QSFP switch, because each unit has only two ports.
How do I know the link is actually running at 200G?
Check ethtool for 200000Mb/s on both halves, set MTU 9000 and pass a jumbo ping with fragmentation forbidden, then measure with ib_write_bw one half at a time and both together. Expect about 111 Gb/s per half and about 196 Gb/s combined. A half reading 12 to 13 Gb/s with a green status is a firmware-throttled NIC: update the OS and firmware and reboot.
Do you ship the DGX Spark cable outside the United States?
Checkout ships to US addresses only, with free shipping. Outside the US, request a quote from the cable page and we reply with shipping options.
Order the cable
The cable that connects two DGX Sparks is one part, and we keep it on the shelf. The Amphenol NJAAKR-0006, a 0.5 m QSFP112 400G passive DAC at 30 AWG, is $159 as a single, $299 as a 2-pack and $435 as the 3-pack ring kit, all with free shipping to US addresses, in stock and shipping in 1 to 3 business days. It fits every GB10 workstation listed above. For five or more cables, a purchase order, or help planning a larger cluster, call Penny at 919-348-4912 or use the quote form on the cable page. If you would rather have the pair built and validated for you, our AI infrastructure team does that work too.
Buy the DGX Spark cluster cable, $159 with free US shipping
Sources: NVIDIA DGX Spark User Guide, ConnectX-7 networking (two QSFP ports, 200 Gb/s per port, approved cables, two PCIe Gen 5 x4 links, interface names, direct up to three and switched up to four); NVIDIA, Connect Two Sparks (one QSFP cable, prerequisites, duration and risk); Petronella Technology Group, Inc., GB10 cluster guide (111.86 and 196.08 Gb/s direct-cable baselines, 12.74 Gb/s throttle, 273 GB/s memory figure, 1,963 / 8.3 versus 539 / 3.5 tok/s comparison, bring-up procedure).
Free, practical, and specific to regulated environments. We will email it to you.
No spam. Unsubscribe anytime.