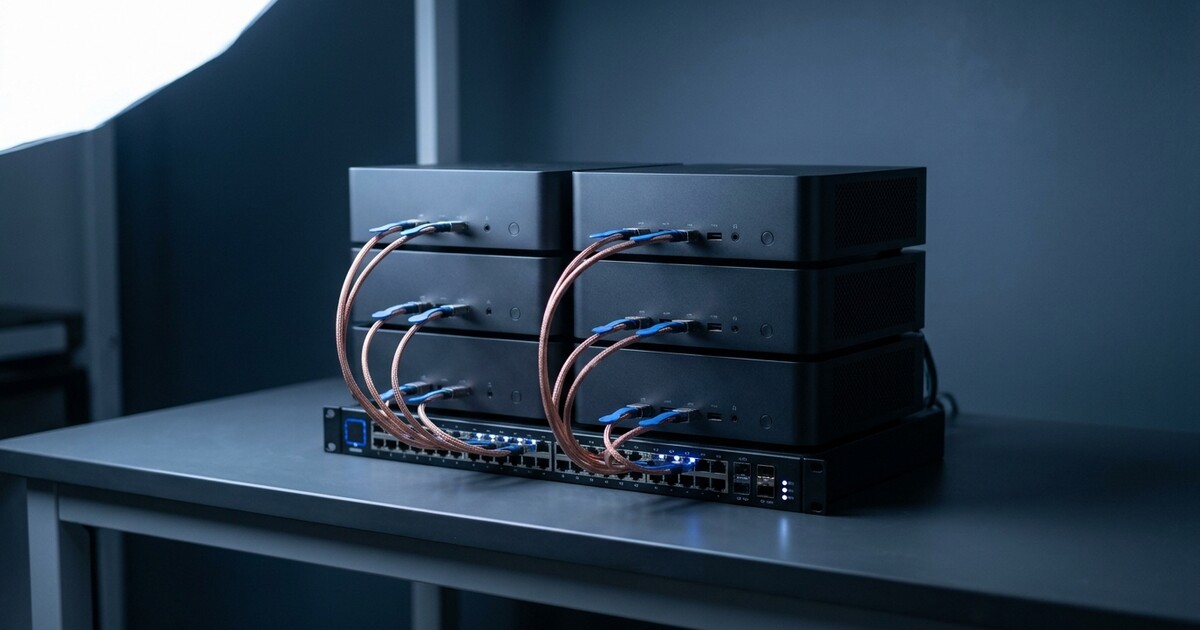
Three DGX Spark units make a switchless cluster with three cables, and the whole job comes down to one rule: every cable joins a Port 0 to a Port 1. Node 1 Port 0 goes to Node 2 Port 1, Node 2 Port 0 goes to Node 3 Port 1, and Node 3 Port 0 goes to Node 1 Port 1. That is the exact cabling in NVIDIA's "Connect Three DGX Spark in a Ring Topology" playbook, and it is the part most write-ups get vague about. This post walks through the DGX Spark ring topology port by port, shows why a cable in the wrong cage breaks NVIDIA's copy-and-paste network configuration even though every link lights up, and gives the checks that prove the ring is running at line rate before you load a model.
We are Petronella Technology Group, Inc. We sell the 0.5 m QSFP112 cluster cable that this topology uses, and we run GB10 workstations in pairs and on a switched fabric in our own lab. Every fact below comes from NVIDIA's playbooks and documentation, from our public GB10 cluster guide, or from owner reports on the NVIDIA developer forum, each linked where it is used.
Get the 3-cable ring kit, $435 shipped
What you need for a three-node DGX Spark ring
NVIDIA's ring playbook lists the prerequisites plainly:
- Three DGX Spark systems. Any GB10 workstation works the same way, because every one of them carries the same ConnectX-7 with two QSFP ports: the Dell Pro Max with GB10, ASUS Ascent GX10, HP ZGX Nano, Lenovo ThinkStation PGX, MSI EdgeXpert, Gigabyte AI TOP ATOM and Acer Veriton GN100. Brands can be mixed in one ring.
- Three QSFP cables for a direct 200GbE connection between the devices.
- SSH access to all three systems, root or sudo on all three, and the same username on all three.
- All three systems updated to the latest OS and firmware.
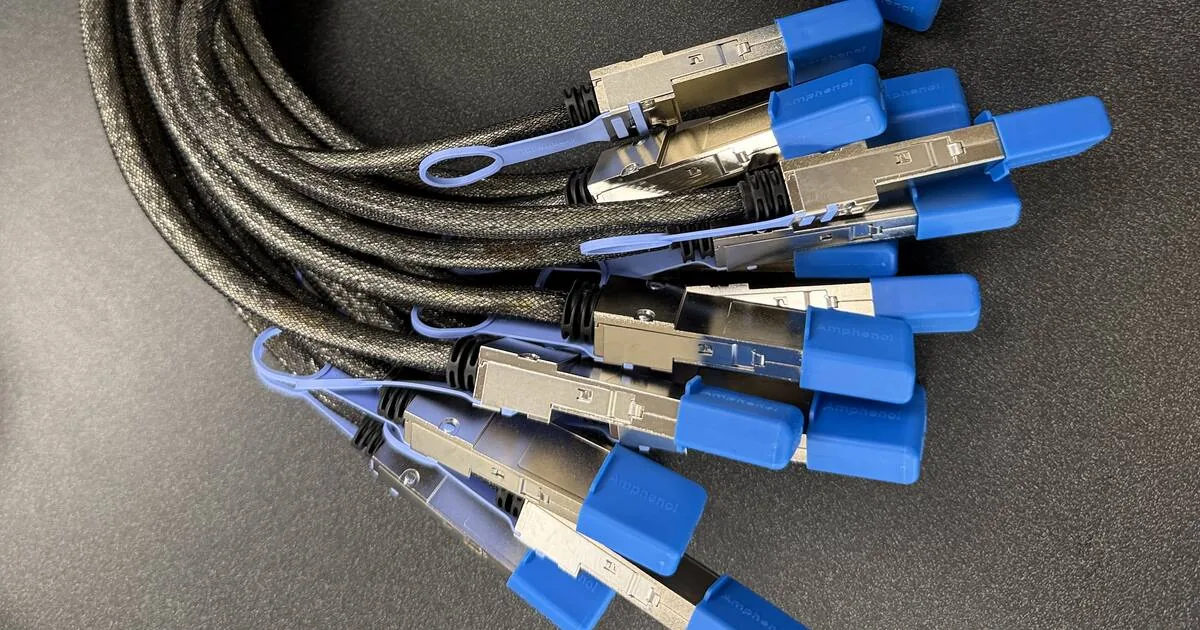
NVIDIA rates the job at one hour including validation, medium risk because it reconfigures the network, and reversible by removing the netplan file. The cable is the same one used to link two units: a 0.5 m QSFP112 passive direct-attach copper cable built to the NVIDIA-approved Amphenol NJAAKK0006 / Luxshare LMTQF022-SD-R specification. It is rated for 400G and links at 200G on a GB10, which is the port's documented ceiling. Our 400G versus 200G explainer covers why the label and the link speed differ.
Three cables at $159 each would be $477. The 3-pack ring kit is $435, or $145 per cable, ships in one box with free shipping to US addresses, and leaves our shelf in 1 to 3 business days.
Find Port 0 and Port 1 before you plug anything in
NVIDIA's DGX Spark user guide defines the two cages: seen from the back of the unit, the left QSFP port, the one closest to the RJ45 Ethernet jack, is Port 0, and the other one is Port 1. The ring playbook says the same thing in different words: "Port0 is the CX7 port next to the Ethernet port and Port1 is the CX7 port further away from it."
Linux names each port twice, because the ConnectX-7 connects to the GB10 chip over two independent PCIe Gen 5 x4 links and every physical port appears once on each link:
- Port 0: Ethernet interfaces
enp1s0f0np0andenP2p1s0f0np0, RDMA devicesrocep1s0f0androceP2p1s0f0. - Port 1: Ethernet interfaces
enp1s0f1np1andenP2p1s0f1np1, RDMA devicesrocep1s0f1androceP2p1s0f1.
The two names for one port are the same wire. Each half carries roughly 100 Gb/s, and the full 200 Gb/s of a cable only shows up when traffic runs on both halves at once. That is why NVIDIA's ring configuration assigns an address to all four interfaces on every node: in the playbook's words, "in a three node ring topology all four interfaces on each node must be assigned an IP address to form a symmetric cluster."
If your GB10 is not a Founders Edition and you are unsure which cage is which, let Linux tell you. Plug in a single cable, run ibdev2netdev, and look at which interfaces report (Up). If enp1s0f0np0 and enP2p1s0f0np0 come up, you are in Port 0. Label the cages with tape, then pull the test cable and wire the ring.
The ring, port by port
Name the units Node 1, Node 2 and Node 3 and write the names on the chassis. Then run the three cables exactly as NVIDIA's playbook lists them:
- Cable 1: Node 1 Port 0 to Node 2 Port 1.
- Cable 2: Node 2 Port 0 to Node 3 Port 1.
- Cable 3: Node 3 Port 0 to Node 1 Port 1.
Read it as a chase: each unit's Port 0 points forward to the next unit's Port 1, and the last unit points back to the first. When you are done, every unit has both cages filled, and every pair of units has its own direct cable. Although NVIDIA calls it a ring, three nodes with three links is a full mesh: no traffic ever has to hop through a third unit. That is the property that makes three the largest switchless cluster. NVIDIA's clustering documentation states that its Sync Cluster Assistant "supports up to three DGX Spark systems connected directly through cables, and up to four systems when using a switch."
The playbook adds a warning in a note box: "Double check that the connections are correct otherwise the network configuration might fail." The next section shows exactly how it fails.
Why a Port 0 to Port 0 cable breaks the configuration
The manual option in NVIDIA's playbook is a netplan file per node. Each file puts a /24 on each of the four interfaces, and the subnets are laid out so that the two ends of every cable land in the same two subnets. Reading the three files side by side gives this map:
- Cable 1, Node 1 Port 0 to Node 2 Port 1: 192.168.0.1 and 192.168.0.2 on the first PCIe half, 192.168.1.1 and 192.168.1.2 on the second.
- Cable 2, Node 2 Port 0 to Node 3 Port 1: 192.168.4.1 and 192.168.4.2 on the first half, 192.168.5.1 and 192.168.5.2 on the second.
- Cable 3, Node 3 Port 0 to Node 1 Port 1: 192.168.2.1 and 192.168.2.2 on the first half, 192.168.3.1 and 192.168.3.2 on the second.
Every cable carries two subnets, one per PCIe half, and each subnet has exactly two members. Now picture a cable from Node 1 Port 0 to Node 2 Port 0. Physically it links fine: ibdev2netdev shows the interfaces Up and ethtool shows 200000Mb/s. But Node 1 Port 0 holds 192.168.0.1 while Node 2 Port 0 holds 192.168.4.1. The two ends of that wire are in different subnets, so nothing on it can reach anything else, and the pair that should have used Cable 1 has no working path. The cluster looks healthy at the link layer and is broken at the IP layer, which is the most confusing kind of fault to chase.
There are two fixes, and both are fine. Move the cable to the cage the playbook expects, or keep your wiring and edit the netplan files so the two ends of each physical cable share a subnet. What does not work is mixing NVIDIA's files with your own cabling. If you choose your own addressing, keep the rule our cluster guide uses everywhere: one subnet per PCIe half per link, and never a default route on a fabric interface. A default route on a fabric interface can pull ordinary traffic onto the cluster link, which is one way a unit seems to lose its internet access as soon as the cables go in.
NVIDIA also offers an automatic option: a cluster setup script in the dgx-spark-playbooks repository (under multi-sparks-through-switch/assets/spark_cluster_setup) that configures the interfaces on all nodes, sets up passwordless SSH, verifies multi-node communication and runs NCCL bandwidth tests. The playbook recommends it "to avoid complexity of network setup." Even with the script, cable the ring as listed above, so the physical layout matches what every NVIDIA example assumes.
Order the ring kit: three cables, one box, free US shipping
Bring-up checks, in order
Each check below rules out a class of fault that the next one would misreport. Run them on all three nodes.
1. All four interfaces Up
With all three cables in, NVIDIA's playbook expects ibdev2netdev to show all four interfaces Up on every node: enp1s0f0np0, enp1s0f1np1, enP2p1s0f0np0 and enP2p1s0f1np1. If any are down, the playbook's advice is to check the QSFP cable connection, reboot the systems and try again.
2. Speed on every interface
Run sudo ethtool enp1s0f0np0 | grep Speed and repeat for the other three interfaces. Each should report 200000Mb/s. A direct cable between two GB10 units does not involve a switch, so there is no switch port to force; a lower number here usually means a seating problem or a firmware issue.
3. Addresses and routes
Run ip -br addr and ip route. You want four fabric addresses per node, one route per fabric subnet, each pointing at an interface with carrier, and no default route on any fabric interface. Stale addresses from an earlier two-node setup are a common leftover. Remove old netplan fragments that still assign addresses to the same interfaces before you apply the ring configuration.
4. Ping every neighbor on both halves
From Node 1, ping 192.168.0.2 and 192.168.1.2 (Node 2 over Cable 1) and 192.168.2.2 and 192.168.3.2 (Node 3 over Cable 3). Repeat from the other nodes with their neighbors' addresses. If you raise the fabric MTU to 9000, which NVIDIA's ring files do not do but our guide recommends for RDMA traffic, set it on both ends of every link and prove it with a ping that forbids fragmentation: ping -M do -s 8972 <peer>. A 1500-byte interface on one end of a 9000-byte link fails quietly.
5. Measure bandwidth, one half at a time
Link lights and pings do not prove throughput. Use ib_write_bw from the perftest package, one RDMA device at a time. On a healthy direct cable we measured 111.86 Gb/s on one PCIe half and 98.04 + 98.04 = 196.08 Gb/s with both halves running at once, which is 98 percent of the 200 Gb/s line rate. The full commands, including how to look up the right RoCE GID index, are in the validation document of our guide. Do not use a single iperf3 TCP stream as a link test: on the GB10's Arm cores one stream sits near 12 Gb/s whatever the cable is doing.
6. If a link is far below line rate
Two causes account for most of the slow new clusters we see reported:
- The first-plug power drain. On a September 2026 NVIDIA forum thread, a new two-unit cluster ran far below speed until the owner powered both units off and unplugged them from the wall for a minute. Afterwards
ib_write_bwreported 110.92 Gb/s. The forum member who suggested it describes it as a common problem the very first time a DAC is plugged in, which does not recur. With three new cables, drain all three units. - Firmware. A throttled ConnectX-7 on one of our units read 12.74 Gb/s on a link that showed 200G in every status tool; an OS and firmware update plus a reboot took it to 111.86 Gb/s. Forum owners also tracked an early-2026 firmware regression that cut NCCL results from about 24 GB/s to about 16 GB/s; it was fixed in the February 2026 update on the Founders Edition, with OEM vendors releasing the fix on their own schedules. Update every node before you benchmark.
NCCL and what a three-node ring can actually run
NVIDIA's playbook ends with an NCCL bandwidth test, run through the same cluster setup script with its --run-nccl-test option. On the software side the community has caught up with the hardware. In April 2026 the maintainers of the widely used spark-vllm-docker project and sparkrun announced three-node mesh support, and by July the project's maintainer reported that its NCCL build comes from the main branch because three-node support had been merged there, so no special branch is needed. If you built a container before that, rebuild it and redistribute it to all three nodes, and use the same image digest everywhere: two nodes pulling "the same" tag on different days can end up with different NCCL builds.
The bigger planning question is parallelism, and three is an awkward number for it. The same maintainer explains on that thread that tensor parallel needs the model's attention head count to divide by the number of ranks, and since models ship with head counts like 64 or 128, powers of two (2, 4, 8) are the practical rule. That leaves three realistic ways to use three units:
- Pipeline parallel across all three. It pools the memory, so a model that needs about 384 GB can load, but on that thread the maintainer notes that three nodes in pipeline parallel can be slower than a single Spark because of the added overhead. You buy capacity, not speed.
- Data parallel. If the model fits on one unit, run a copy on each unit and triple the number of concurrent requests you can serve. The ring still matters for moving weights between nodes quickly.
- A tensor-parallel pair plus a third node. Run a two-node tensor-parallel model at the same speed as a two-node cluster, and give the third unit embeddings, reranking, a small fast model, or other jobs.
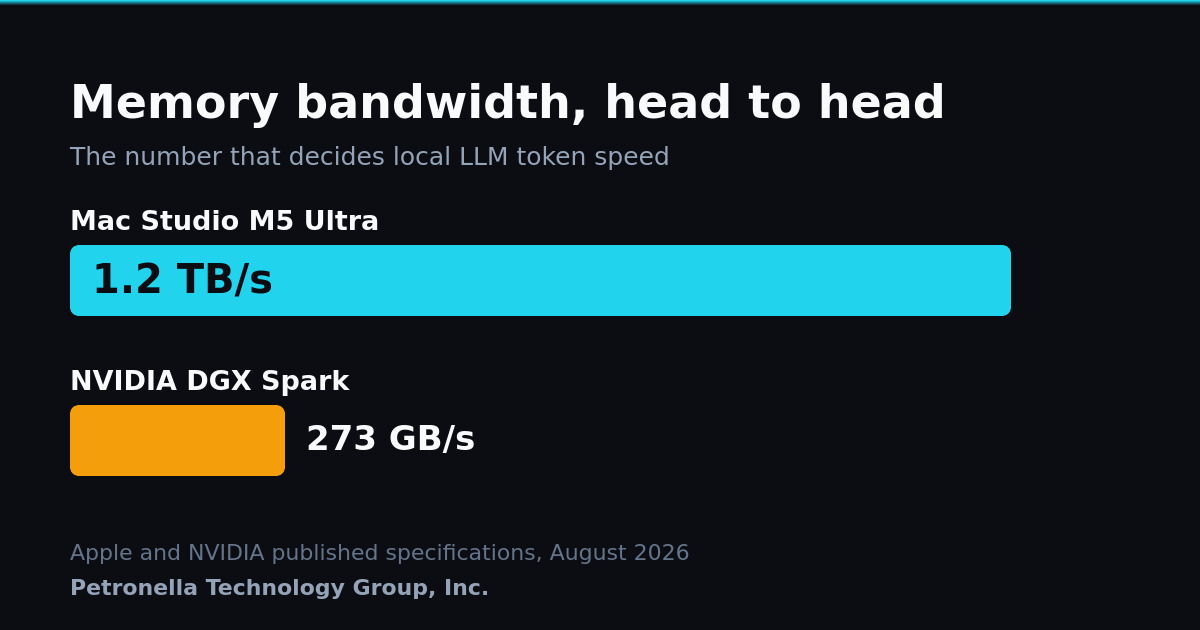
This matches what we see on our own hardware and what we wrote in our bandwidth explainer: each GB10 has 273 GB/s of memory bandwidth and each link carries about 25 GB/s, so clustering is a capacity play first. A single unit runs models up to roughly 200B parameters, two linked units up to about 405B, and a third unit adds another 128 GB of unified memory.
Three nodes or a switch?
The ring is the cheapest way past two units: three cables and no switch, no rack space and no switch configuration. It stops at three. With two QSFP ports per unit, a fourth node cannot have a direct link to every other node, and we confirmed it the hard way: four units wired as four point-to-point links left the two non-adjacent units with no route to each other. NVIDIA supports up to four units through a switch.
If you already know you want four, it can make sense to skip the ring. Four nodes are a power of two, so tensor parallel 4 works where three would not, and the switch build reuses the same cable, one per node. We measured the switch penalty at about 0.7 percent per PCIe half (109.11 Gb/s through the switch against 111.86 Gb/s direct). Our four-node switch versus ring comparison covers the decision and the parts list, our switched-fabric write-up covers the switch configuration traps, and if you start with the ring and add a switch later, the three ring cables move straight onto the switch.
Cable length and physical layout
A 0.5 m cable is about 19 inches. That covers units stacked on each other or sitting side by side, which is how most three-unit desks and shelves are laid out. In a ring, Cable 3 runs from the last unit back to the first, so in a stack it spans two unit heights rather than one; lay the three units out and route the longest run before you order if your stack is tall or the units are spread out. If the units sit apart, for example separated by a monitor or on two shelves, longer lengths (1 m, 2 m, and 3 m active copper) are built to order through the cable page. The cable is passive copper with no firmware, so it adds essentially no latency and no power draw, and there is nothing to update.
If your units are a specific brand, the vendor pages carry the fit notes for each chassis: Dell Pro Max GB10, ASUS Ascent GX10, HP ZGX Nano, Lenovo ThinkStation PGX, MSI EdgeXpert, Gigabyte AI TOP ATOM and Acer Veriton GN100. It is the same cable on all of them.
Quick answers
What is the correct cabling for a three-node DGX Spark ring? Node 1 Port 0 to Node 2 Port 1, Node 2 Port 0 to Node 3 Port 1, Node 3 Port 0 to Node 1 Port 1. Every cable joins a Port 0 to a Port 1.
Which port is Port 0? The QSFP cage next to the RJ45 Ethernet jack, the left one when you look at the back of a DGX Spark. Linux calls it enp1s0f0np0 and enP2p1s0f0np0.
How much does the ring cost in cables? Three cables. Petronella Technology Group, Inc. sells them as a ring kit for $435, $145 per cable, with free US shipping, shipping in 1 to 3 business days.
Is a three-node ring a full mesh? Yes. Three nodes and three cables give every pair its own direct link, so no traffic crosses a third unit.
Frequently asked questions
How do you wire three DGX Sparks in a ring?
Use three QSFP cables and connect each unit's Port 0 to the next unit's Port 1: Node 1 Port 0 to Node 2 Port 1, Node 2 Port 0 to Node 3 Port 1, and Node 3 Port 0 to Node 1 Port 1. Port 0 is the ConnectX-7 port next to the RJ45 Ethernet port. This is the cabling in NVIDIA's Connect Three DGX Spark in a Ring Topology playbook.
Does it matter which QSFP port I use in a three-node DGX Spark ring?
Yes, if you use NVIDIA's netplan files. Each cable must join a Port 0 to a Port 1, because the playbook puts the matching /24 subnets on those two interfaces. Wire Port 0 to Port 0 and every interface still shows Up, but the two ends sit in different subnets and ping fails.
How many cables does a three-node DGX Spark cluster need?
Three. Each unit uses both of its QSFP ports, and every pair of units gets its own direct link, so the ring is a full mesh with no switch. Petronella Technology Group, Inc. sells the three cables as a ring kit for $435 with free US shipping.
Can three DGX Sparks run tensor parallel across all three nodes?
Usually not. Tensor parallel needs the model's attention head count to divide by the number of ranks, which in practice means 2, 4 or 8. Three nodes are normally run as pipeline parallel, as data parallel copies of a model that fits one unit, or as a tensor parallel pair plus a third unit serving other work.
Why is my new DGX Spark ring slow right after I plugged in the cables?
Owners on the NVIDIA developer forum report that the first time a DAC is plugged in, the ConnectX-7 can run far below line rate until the unit is fully powered off and unplugged from the wall for about a minute. After the power drain one owner measured 110.92 Gb/s. Also update the OS and firmware on all three units, which NVIDIA lists as a prerequisite.
Can I add a fourth DGX Spark to the ring?
Not as a full mesh. Each unit has two QSFP ports, and four nodes need three links each for every pair to connect directly. NVIDIA supports up to three units on direct cables and up to four through a switch.
Order the ring kit
The ring kit is our most common multipack, and the build needs nothing but three cables and about an hour. Our 0.5 m QSFP112 cable is built to the NVIDIA-approved spec, fits every GB10 workstation, and is in stock. The 3-pack ring kit is $435, a single cable is $159 and a 2-pack is $299, all with free shipping to US addresses and shipping in 1 to 3 business days. For five or more cables, a purchase order, or help planning a larger cluster, call Penny at 919-348-4912 or use the form on the cable page. If you would rather have the cluster built and validated for you, our AI infrastructure team does that work too.
Buy the DGX Spark ring kit, $435 with free US shipping
Sources: NVIDIA, Connect Three DGX Spark in a Ring Topology (cabling, prerequisites, netplan files, duration and risk); NVIDIA DGX Spark User Guide, ConnectX-7 networking (port numbering, 200 Gb/s per port, approved cables, three direct and four switched); Petronella Technology Group, Inc., GB10 cluster guide (measurements and validation commands); NVIDIA developer forum threads 365296, 362403 and 383649.
Free, practical, and specific to regulated environments. We will email it to you.
No spam. Unsubscribe anytime.