DGX Spark has 273 GB/s of memory bandwidth from its 128 GB of LPDDR5x unified memory, and the 400G QSFP112 cluster link between two Sparks moves data at about 25 GB/s, roughly a tenth of that; we measured 196 Gb/s over a single 0.5 m DAC with two RDMA streams running. Clustering two units therefore adds memory capacity for larger models rather than speed for a model that already fits in one. The cable is a 0.5 m QSFP112 400G passive DAC, Amphenol NJAAKR-0006, 30 AWG: one cable links two units and three cables make a switchless three-node ring.
Short answer: the DGX Spark has 273 GB/s of memory bandwidth, from 128 GB of LPDDR5x unified memory on a 256-bit interface that the GB10 Grace Blackwell CPU and GPU share. The 400G cluster link is a different number: two Sparks joined by the DGX Spark cluster cable talk at about 25 GB/s, roughly a tenth of that, which is why clustering adds memory capacity rather than speed.
Here is a number that quietly trips up nearly every engineer pricing out an NVIDIA DGX Spark cluster: the cable that connects two of these little Grace Blackwell machines is stamped 400G, and almost everyone reads that as four hundred something-fast and moves on. The trouble is what they assume that number buys them. They picture a firehose. What they actually get, once you do the arithmetic the marketing never shows you, is a garden hose with very good pressure. This is the single most misunderstood spec in the entire desktop AI cluster conversation, and getting it wrong leads people to overspend on hardware, expect performance that physics will not deliver, and design clusters around the wrong goal entirely.
We sell the 0.5m QSFP112 400G DAC cluster cable that links two DGX Spark workstations, so we field this question constantly. And the honest answer is more interesting than the hype. The cable is not the bottleneck, the headline bandwidth is not what you think, and the reason to cluster two Sparks has nothing to do with going faster. Let us walk through exactly what is happening, with real NVIDIA numbers, so you can make a clear-eyed decision before you spend four or five thousand dollars on a second node.
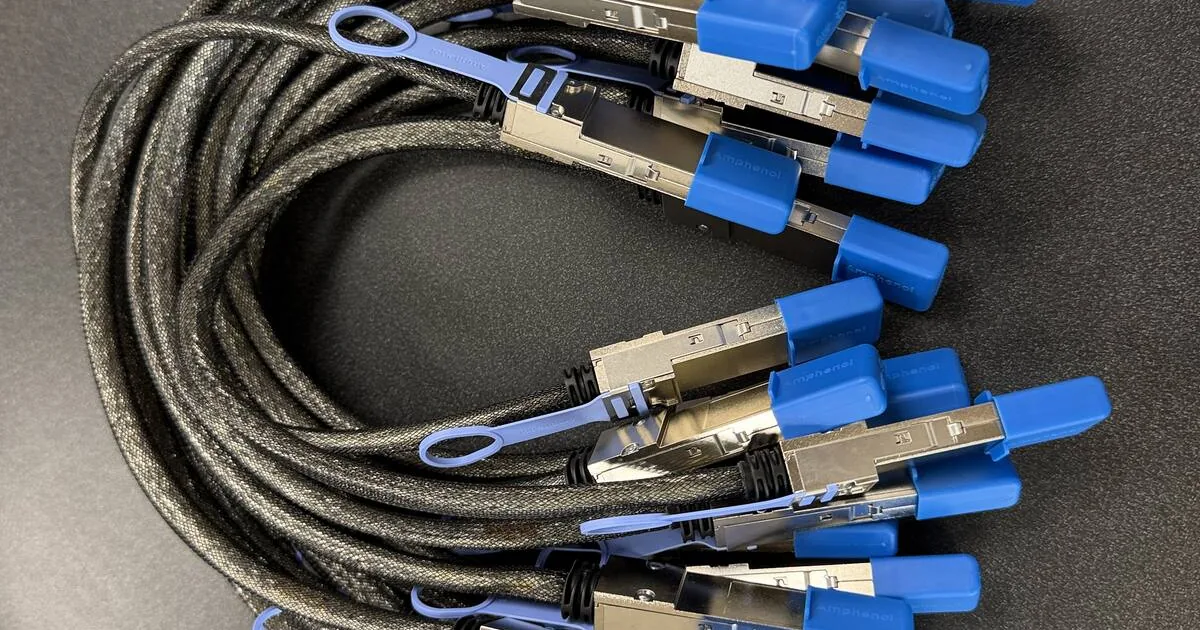
The cable this article is about: the 0.5m QSFP112 400G DAC cluster cable for DGX Spark and every GB10 workstation is $159* with free US shipping, in stock, and ships in 1 to 3 business days. It is built to the NVIDIA-approved Amphenol NJAAKK0006 / Luxshare LMTQF022-SD-R spec. One cable links two Sparks; three cables make a switchless three-node ring.
Buy now, $159 shipped or see specs, multipacks and Apple Pay / Google Pay checkout for part NJAAKR-0006.
Bits versus bytes: the division nobody does
Start with the conversion that causes ninety percent of the confusion. Network speeds are measured in bits per second. Memory bandwidth, disk throughput, and the size of the model weights you are trying to move are measured in bytes per second. There are eight bits in a byte. That factor of eight is the whole story.
So when a cable or a NIC says 400 Gbps, the real ceiling in the units you actually care about is:
- 400 Gbps divided by 8 equals 50 GB/s. That is the cable's rated ceiling in gigabytes per second.
- 200 Gbps divided by 8 equals 25 GB/s. Hold onto this one, because as you will see in a moment, 200 is the number that actually applies to a DGX Spark.
- 100 Gbps divided by 8 equals 12.5 GB/s. This matters too, because of how the Spark splits its link.
Then subtract protocol overhead. Even efficient remote direct memory access (RDMA) transports do not hit the theoretical line rate. A realistic, defensible efficiency band is about 85 to 92 percent of nameplate once you account for headers, acknowledgements, and the realities of moving data between two physical machines. So the usable byte rate is always meaningfully below the already-divided-by-eight figure. People who skip the division are off by 8x before they even start. People who skip the overhead are off by another ten percent on top of that.
None of this means the cable is bad. It means the headline bit number and the practical byte number are two very different things, and you have to translate one into the other before you can reason about whether a cluster will do what you want.
The plot twist: a DGX Spark link is not 400G, it is 200
This is where the gold is, and where most online discussions are simply wrong. The cable is rated for 400G. The NIC inside the DGX Spark is not.
Each DGX Spark ships with an NVIDIA ConnectX-7 Smart NIC exposed as two QSFP network ports. According to NVIDIA's own DGX Spark hardware documentation, the supported interconnect for directly connecting two Spark systems runs at 200 Gb/s, not 400. The ConnectX-7 silicon in this product is operating as a 200GbE-class part. The 400G printed on the cable is a ceiling the cable can support, not a speed the Spark will ever negotiate. The cable is over-provisioned on purpose, which is good engineering, but it does not raise the NIC's limit.
It gets more nuanced, and the nuance matters for how you wire it. Hardware teardowns of the GB10 platform show the ConnectX-7 is fed by the GB10 system-on-chip over two PCIe Gen5 x4 links, each delivering roughly 100 Gbps. NVIDIA attributes this to a limit in the GB10 SoC, which does not provide more than an x4-wide PCIe path per device. The practical consequence: the NIC presents as multiple 100G channels, and to reach the full roughly 200 Gb/s between two Sparks you need traffic on both PCIe halves of the port in parallel. Mentally, treat it as two times 100G behind one connector, not as a single clean 200G or 400G pipe. One cable carries both halves: we measured 196 Gb/s across a single 0.5m DAC with two RDMA streams running, so a second cable to the same neighbor adds nothing. The second QSFP port is what lets a third unit join a switchless ring.
What do you actually measure in the real world? Field reports of point-to-point RoCE (RDMA over Converged Ethernet) throughput between two DGX Sparks land around 185 to 190 Gb/s, with a broader range of roughly 160 to 198 Gb/s depending on tuning. Convert the realistic figure to bytes: about 23 to 24 GB/s of usable cross-node bandwidth. That is the real number. Not 400, not 50. About 23 to 24 gigabytes per second, when everything is configured well.
If you remember one thing, remember this: the cable is 400G, the link is 200G, the bytes are about 25, and the measured reality is about 23.
The number that actually matters: 273 GB/s versus 25 GB/s
Knowing the cross-node link is about 25 GB/s is only half the insight. The other half is comparing it to the bandwidth inside a single Spark, because that comparison tells you whether clustering helps or hurts a given workload.
The GB10 Grace Blackwell Superchip carries 128 GB of LPDDR5x unified system memory on a 256-bit interface at 4266 MHz, delivering 273 GB/s of memory bandwidth, per NVIDIA's published hardware overview. That 273 GB/s is how fast the chip can stream model weights and activations out of its own memory. It is the heartbeat of inference and training on a single node.
Now put the two numbers side by side:
- Inside one Spark: 273 GB/s memory bandwidth.
- Between two Sparks: about 25 GB/s nameplate; a single cable measured 196.08 Gb/s (about 24.5 GB/s) on our own fleet with both PCIe halves running, and 111.86 Gb/s (about 14 GB/s) on one half.
The link between nodes is roughly eleven times slower than the memory inside a single node on nameplate math, and closer to twenty times slower against the single-cable figure we measure on our own fleet. Any operation that has to cross that cable, splitting a layer across both machines, synchronizing weights, exchanging activations, is throttled to a fraction of the speed at which each node can work locally. The interconnect is the bottleneck, full stop. When work stays on one node it runs at memory speed. The instant it has to traverse the wire, it slows to the wire's pace.
There is one more bandwidth figure worth separating out, because conflating it with the others is the most common technical error we see. The GB10 also has an NVLink-C2C interconnect rated around 600 GB/s. That is the chip-to-chip link between the Grace CPU tile and the Blackwell GPU tile inside a single package. It is not your network. It does not stretch across a cable to a second Spark. So a single Spark enjoys a 600 GB/s internal CPU-to-GPU path and 273 GB/s to its memory, while two Sparks talk to each other at about 25 GB/s. Three very different numbers, three very different jobs. Keep them straight and the whole architecture suddenly makes sense.
What we actually measure on our own GB10 fleet
Everything above is arithmetic you can do from spec sheets. This part is not. Petronella Technology Group runs four GB10 machines in production, two MSI EdgeXpert MS-C931 units and two DGX Sparks, clustered in pairs over the exact 0.5m QSFP112 DAC cable this article is about, and we benchmark the links directly.
Out of the box, both pairs measured a shocking 13 Gb/s node to node. That was not the cable and not the spec: it was a known NVIDIA driver bug (driver 580.142 with kernel 6.17.0-1014) that silently throttled the ConnectX-7. After a full system upgrade to driver 580.159.03 and kernel 6.17.0-1018, the same cable on the same machines measured 111.86 Gb/s of RDMA throughput, about 14 GB/s, on both pairs. If your Spark cluster feels slow, check the driver before you blame the hardware.
Why 111.86 and not 200? That figure is one PCIe half. The GB10 feeds its ConnectX-7 through two PCIe Gen5 x4 links, and each QSFP port appears in Linux as two interfaces, one per link, each good for roughly 100 Gb/s. A single ib_write_bw process drives one half. Run one on each half at the same time and the same single cable measured 98.04 + 98.04 = 196.08 Gb/s, about 24.5 GB/s, which is 98 percent of the 200 Gb/s line rate. NCCL uses both halves on its own when you list both RDMA devices. So the honest planning number for a single-cable, two-Spark link is about 23 to 24 GB/s once protocol overhead is counted, with about 14 GB/s only if a workload drives one half. The commands are in our GB10 cluster guide.
We publish these numbers because we sell the cable and run the hardware, and the honest figure serves buyers better than the nameplate. Every cable we ship is the same part we benchmark in our own racks.
So why cluster two Sparks at all? Capacity, not speed
If the link is the slow part, why would anyone connect two of these machines? Because clustering a pair of Sparks was never about making inference faster. It is about making a bigger model fit.
NVIDIA's own framing is explicit. A single DGX Spark with its 128 GB of unified memory runs models up to roughly 200 billion parameters. Connect two Sparks and the combined memory pool lets you run models up to 405 billion parameters, the dual-Spark configuration NVIDIA documents. The cable does not speed anything up. It pools two pools of memory so a model that is physically too large for one 128 GB node can spread across two nodes and run at all.
This is the mental model to carry into any purchase decision. Two clustered Sparks running a 405B model will be slower per token than one Spark running a model that fits comfortably in 128 GB, because the big model is paying the cross-node tax on every step. You accept that slowdown in exchange for the ability to run a model you otherwise could not load at all. Capacity, not speed. If your model already fits on one node, a second node and a cable will not make it faster, and in many cases will make it slower. If your model does not fit, the second node is the only way to run it locally instead of renting cloud GPUs.
This reframing changes how you should shop. The value of a two-Spark cluster is unlocking a class of model, not chasing throughput. We make the same point when clients compare desktop options in our RTX PRO 6000 Blackwell versus GB10 Grace benchmark: the right machine depends on whether you are memory-capacity bound or compute bound, and those are different problems with different answers.
Two nodes, not three: the topology truth
Here is a place where the conventional wisdom recently changed. People hear cluster and imagine a ring of many Sparks lashed together with cables into a little supercomputer on a desk. Direct cabling does now support a two-node link and a switchless three-node ring, but it stops at three, and the bandwidth math below explains why even the three-node ring is not the desktop supercomputer people picture.
NVIDIA documents two switchless, cable-only topologies: a direct link between two Sparks, and a three-node ring (its "Connect Three DGX Spark in a Ring Topology" playbook), where each Spark uses both QSFP ports and three cables form a full mesh. Three nodes is the ceiling, because each Spark has only two QSFP112 ports and a fourth node cannot be cabled directly to all the others. To go past three nodes you add an external switch, along with the cost, the rack space, the power, the configuration, and the latency that a switch brings.
This is worth knowing before you buy a third machine to build a ring. The three-node ring is now a supported direct-cable topology, but the per-link bandwidth we covered above means the result is communication-bound and scales sub-linearly. Ring-based collective operations are actually the bandwidth-optimal pattern in distributed training, which is why frameworks use them, so the topology idea is not crazy in principle. The limiter is not the ring, it is the roughly 25 GB/s per link. Spending four or five thousand dollars on a third node to validate a ring usually buys you an honest but unimpressive result: yes, it is communication-bound, exactly as the math predicts. If your goal is to run larger models, two nodes is the documented, supported, cost-effective configuration. If your goal is many nodes, you are now building a switched cluster and a very different budget conversation, which is the kind of design work our AI infrastructure team does with clients every week.
Where the cable fits, and why it is never the bottleneck
Given all of this, where does the actual cable sit in the picture? Comfortably, and cheaply. The part you need is a 0.5m QSFP112 400G passive direct attach copper cable, Amphenol NJAAKR-0006, 30 AWG; full specs, OEM compatibility, and ordering live on the cable page linked above. Passive DAC means there are no retimers, no digital signal processing, no firmware, just well-shielded twinax copper. That gives you near-zero added latency, well under a tenth of a watt of power draw, and total reliability, with nothing to fail or to update.
Because the cable is rated to 400G and the NIC only asks for 200, the cable is over-provisioned and backward compatible. It will never be the limiting factor in your cluster. The ConnectX-7 is the ceiling, the GB10 SoC's PCIe width is the ceiling, the bits-to-bytes math is the ceiling. The cable just faithfully carries whatever the NIC negotiates, with margin to spare. That is precisely what you want in a passive interconnect: a component that is not the weak link.
The frustrating part for buyers has never been the cable's capability. It has been availability and price. This specific short QSFP112 DAC was backordered at most distributors for months after the GB10 platform launched, and was often quoted at $176 to $285 at the time. We bought a quantity so builders are not stuck. The price is $159 with free shipping in the United States* (we ship to US addresses only; international orders are quoted separately), and we keep them on the shelf.
Order today: Buy the 0.5m QSFP112 400G DAC for $159. One cable carries the full link between a pair of Sparks; a switchless three-node ring takes three. Need volume pricing on five, ten, or twenty units, or a longer length? Call Penny at 919-348-4912 and we will quote you.
Is your DGX Spark cluster link slow? Seven checks, in order
If two linked Sparks feel slow, the fabric is either running at line rate and the workload is memory-bound, which is the math above, or the link is not at line rate. Rule out the second case first. Each check below catches a fault the next one would misreport.
1. Is the link up at 200G?
Run ibdev2netdev and sudo ethtool enp1s0f0np0 | grep Speed on both units. You want the interfaces on the cabled port reporting Up and 200000Mb/s. Use the same QSFP port on both machines: NVIDIA's "Connect Two Sparks" playbook says to use the same physical port on each device to prevent issues with NCCL tests. Through a switch, NVIDIA's switch playbook warns that auto-negotiation may settle at 100000Mb/s; set 200G on the switch port manually with auto-negotiation off.
2. Did you power-drain after the first plug-in?
Owners on the NVIDIA developer forum report that the first time a DAC is plugged into a new Spark, the ConnectX-7 can run far below line rate until the unit is fully powered off and unplugged from the wall for about a minute. In a September 2026 thread this took a new pair to 110.92 Gb/s on one half.
3. Are the OS and firmware current on both units?
A firmware power-throttled ConnectX-7 on one of our units measured 12.74 Gb/s on a link that looked perfect in every status tool; an update and reboot took it to 111.86 Gb/s. Forum owners also tracked an early-2026 firmware regression that cut NCCL results from about 24 GB/s to about 16 GB/s, fixed in the February 2026 update on the Founders Edition, with OEM vendors shipping the fix on their own schedules.
4. Are you measuring with the right tool?
A single iperf3 TCP stream on the GB10's Arm cores sits near 12 Gb/s no matter what the link can do, which looks exactly like a throttled NIC. Measure with ib_write_bw from the perftest package. Expect about 111 Gb/s on one PCIe half over a direct cable and about 196 Gb/s with both halves running at once.
5. Are both PCIe halves configured?
Each QSFP port shows up as two interfaces, enp1s0f0np0 and enP2p1s0f0np0 for Port 0. Give both an address, and list both RDMA devices (for Port 0, rocep1s0f0 and roceP2p1s0f0) in NCCL_IB_HCA. Configure only one and you will top out near 111 Gb/s. A second cable between the same two units does not help, and a forum member notes that running the two-node playbook with a second cable limits bandwidth to 100 Gb/s.
6. Does a jumbo ping pass?
If you use MTU 9000, it must be set on both ends and on every switch port in between. Prove it with ping -M do -s 8972 <peer>. A path with a 1500-byte hop fails this test while normal pings still work.
7. Is the model actually using the fabric?
Read the RDMA byte counters before and after a run. During a two-node Qwen3.8-Flash-Next run, 11 GB crossed the RDMA device on our head node. If the counter does not move, NCCL fell back to sockets over the management network. We measured what that costs: a dense 27B model that decodes at 8.3 tok/s on one unit fell to 3.5 tok/s sharded across four units over 10 Gb/s Ethernet.
If all seven checks pass and the cluster is still slower per token than one unit, the link is fine and the workload is doing what the 273 GB/s versus 25 GB/s math predicts. The full commands for every check are in our free GB10 cluster guide, and if the cable itself is the question, ours is built to the NVIDIA-approved spec and ships in 1 to 3 business days.
Why is my DGX Spark cluster slow? Most often the link is below line rate: a new cable that needs a full power drain, outdated ConnectX-7 firmware, only one PCIe half configured, or a switch port that negotiated 100G. Measure with ib_write_bw, expect about 196 Gb/s with both halves, then look at the workload.
What this means before you spend a dollar
Let us turn the physics into a short buyer's checklist, because the whole point of understanding bits versus bytes is making a better decision.
- Does your model fit in 128 GB? If yes, you do not need a second node or a cable for capacity. One Spark runs it at full 273 GB/s memory speed. Adding a node will not make it faster.
- Is your model larger than one node can hold, up to about 405B parameters? Then a second Spark plus the cable is the documented way to run it locally. Expect capacity, not a speed boost, and budget one cable per pair; a second cable to the same neighbor does not add bandwidth.
- Are you tempted to build a four-plus node ring with cables? Reconsider. Direct cabling supports two or three nodes (a pair or a switchless ring); four or more mean a switch and a different design. And even a three-node ring is communication-bound, so do not expect it to behave like one bigger machine.
- Worried the cable is your bottleneck? It is not. The NIC at 200 Gb/s and the bits-to-bytes math are. The 400G cable has headroom to spare.
- Comparing Spark clusters to a single bigger GPU box? Sometimes one workstation with more local memory bandwidth beats two networked Sparks for your specific workload. We work through that tradeoff in our coverage of GPU data-science workstations and Ollama versus vLLM live benchmarks on Blackwell.
The builders who get the most out of DGX Spark hardware are the ones who internalize that a desktop AI cluster is a memory-capacity machine first and a throughput machine second. The interconnect exists to let memory pools combine, not to pretend two boxes are one fast box. Once you see it that way, the 400G label stops being a promise of speed and becomes what it actually is: a perfectly capable, over-provisioned, inexpensive copper cable doing a quiet, reliable job at the edge of a 200 Gb/s link.
If you are designing something more ambitious than a pair of Sparks, multi-node training, switched fabrics, GPU servers, or production inference, that is squarely what we do. From single-workstation tuning to GPU server hosting and full AI agent development, Petronella Technology Group helps teams build infrastructure that matches the math instead of the marketing. And if you want the broader context on where this class of hardware is heading, our piece on how NVIDIA DGX is sparking the next wave of GPU AI is a good companion read.
Frequently asked questions
Is the DGX Spark cluster cable really 400 Gbps?
The cable is rated for 400G, but the DGX Spark's ConnectX-7 NIC negotiates the link at 200 Gb/s class, delivered as two 100G channels over PCIe Gen5 x4 paths. The 400G figure is the cable's ceiling, not the speed two Sparks actually communicate at. The cable is over-provisioned on purpose and is never the bottleneck.
How much real bandwidth do two linked DGX Sparks get?
About 25 GB/s at the 200 Gb/s nameplate, and about 23 to 24 GB/s in practice. On our own GB10 fleet one cable measured 196.08 Gb/s with both PCIe halves running (98.04 + 98.04), and 111.86 Gb/s, about 14 GB/s, on a single half. NCCL uses both halves when you list both RDMA devices. Divide the headline bit number by eight to get bytes, then subtract overhead.
Why is a 400G link only 50 GB/s?
Networking is quoted in bits per second while memory and storage are quoted in bytes per second, and there are eight bits in a byte. So 400 gigabits per second equals 50 gigabytes per second before overhead, and a 200 Gb/s link equals 25 GB/s.
Does clustering two DGX Sparks make them faster?
No. Clustering pools memory so you can load a model too large for a single 128 GB node. One Spark runs models up to about 200B parameters; two linked Sparks reach up to 405B. A model spread across two nodes pays a cross-node cost on every step, so it is slower per token than a model that fits on one node. You cluster for capacity, not speed.
Can I cluster three or more DGX Sparks with cables?
NVIDIA documents both a two-node direct link and a switchless three-node ring (the "Connect Three DGX Spark in a Ring Topology" playbook, three cables, each Spark using both QSFP ports). Three nodes is the switchless ceiling; four or more units require an external switch. Keep in mind that every cable link is only about 25 GB/s, so a three-node ring is communication-bound and is a capacity play, not a speed boost.
Do I need one cable or two between two DGX Sparks?
One. Each QSFP port presents as two 100G channels over its own PCIe Gen5 x4 link, and one cable carries both: we measured 196 Gb/s between two units over a single 0.5m DAC with two RDMA streams running. A second cable to the same neighbor does not add bandwidth. The second port is for a third unit in a switchless ring.
What cable do I actually need to connect two DGX Sparks?
A 0.5m QSFP112 400G passive direct attach copper (DAC) cable, Amphenol NJAAKR-0006, 30 AWG. We sell them at $159 with free shipping in the United States*. It is in stock and ships in 1 to 3 business days. One cable links two Sparks; a switchless three-node ring takes three. The one-page answer is what cable you need to connect two DGX Sparks.
Is the cable the bottleneck in a DGX Spark cluster?
No. The bottleneck is the ConnectX-7 link at 200 Gb/s and the bits-to-bytes math, which together cap cross-node bandwidth near 23 to 25 GB/s. That is roughly eleven to twelve times slower than the 273 GB/s of memory bandwidth inside a single node. The 400G cable has headroom to spare and faithfully carries whatever the NIC negotiates.
Build it on the math, not the marketing
The 400G label on a DGX Spark cluster cable is not a lie, it is just widely misread. Translate bits to bytes, learn that the real link is 200 Gb/s class and about 25 GB/s in practice, recognize that the interconnect is an order of magnitude slower than each node's own memory, and the right strategy becomes obvious. Cluster two Sparks to run models that do not fit on one. Do not expect a speed boost. Do not build a cable ring of three. And buy a cable that is over-provisioned, reliable, and cheap, because it is the one part of this stack that will never let you down.
Get the cable that connects your cluster: Buy the 0.5m QSFP112 400G DAC for $159. Questions about your build, volume pricing, or cross-border shipping? Call Penny at 919-348-4912 and the Petronella Technology Group team will help you design it right.
* The $159 US price includes free standard shipping (up to a $20 shipping and handling allowance). Shipping and handling rates are subject to change at any time, and a separate shipping invoice may be sent after an order is placed if the actual shipping cost exceeds the included allowance (for example remote US destinations, expedited, oversized, or international orders). Canadian and international recipients are responsible for all customs duties, taxes, and import fees.
Free, practical, and specific to regulated environments. We will email it to you.
No spam. Unsubscribe anytime.