DGX Spark vs Strix Halo is the most common question we get from teams that want to run large language models on their own hardware, and in 2026 it gained a third option: AMD's Gorgon Halo, sold as the Ryzen AI Max PRO 400 series. All three put a CPU and a GPU on one package that share a large pool of LPDDR5X memory, so a single quiet desktop or laptop can hold a model that would otherwise need a rack of graphics cards. They are not interchangeable. This guide compares NVIDIA's GB10 (the chip inside the DGX Spark, the MSI EdgeXpert and other partner boxes), AMD's Strix Halo (Ryzen AI Max 300) and AMD's Gorgon Halo on the things that decide a purchase: memory, speed for one user and for many, software, clustering, reliability and price. Where we have our own measurements, we use them and say so. Where we rely on someone else's numbers, we label them as third-party. Where something is only reported or rumored, we say that too.
Some background on where our numbers come from. We run a pod of eight GB10 systems (four NVIDIA DGX Spark and four MSI EdgeXpert units) for model testing, and we have used three Strix Halo machines in our lab in 2026: an HP ZBook Ultra G1a laptop and two Strix Halo mini desktops, one on Linux and one on Windows. We have not tested a Gorgon Halo system, because as of September 27, 2026 we could not find one shipping to customers. Our measured results feed the self-hosted LLM benchmarks we publish.
Which should you buy: DGX Spark, Strix Halo or Gorgon Halo?
Buy a DGX Spark or another GB10 system if several people will share the machine, if your prompts are long (retrieval, coding agents, document review), or if your work must carry over to NVIDIA data center GPUs. Buy a Strix Halo system if you are one user who wants the lowest price for 128 GB, needs Windows, or wants a laptop. Consider Gorgon Halo only if you need more than 128 GB in an AMD system and can wait for systems to ship.
- Team server, long prompts, CUDA work: DGX Spark or another GB10 system.
- One user, chat and writing, tight budget: a Strix Halo mini desktop running a mixture-of-experts model.
- A private model on a laptop, or a Windows shop: Strix Halo now, Gorgon Halo later.
- Models too large for one box: a GB10 cluster over its 200 Gb/s ports, or a private AI cluster with discrete GPUs if you need production throughput.
Not sure which platform fits your workload? Tell us your models, your number of users and your security requirements, and we will recommend a platform from our own test results. Talk to our team
Key takeaways
- Single-user speed is close. Token generation on all three is limited by memory bandwidth, and they sit in the same class: 273 GB/s on paper for GB10, 256 GB/s for Strix Halo, and 273 GB/s for Gorgon Halo when it runs its memory at the full rated speed. In our same-day test with identical software and model files, a DGX Spark generated text 11 to 19 percent faster than our Strix Halo laptop on dense models and 17 to 41 percent faster on mixture-of-experts models, and we measured its delivered memory bandwidth at 259 GB/s against the laptop's 234 to 235 GB/s.
- Prompt processing and many users are where GB10 pulls away. Reading a long prompt is compute-bound, and GB10 has far more AI compute. With the same llama.cpp build, our DGX Spark read prompts 1.8 to 3.8 times as fast as our Strix Halo laptop, independent reviewers measured the DGX Spark at up to 8.8 times a Strix Halo system on a prefill-heavy serving test, and one GB10 in our pod serves about 590 to 620 tokens per second to 32 users at once.
- Gorgon Halo is a refresh, not a new architecture. AMD confirms the same Zen 5 CPU and RDNA 3.5 graphics as Strix Halo, with faster LPDDR5X-8533 memory and up to 192 GB. More capacity and slightly more bandwidth; the same compute class.
- Strix Halo and Gorgon Halo win on flexibility, and Strix Halo on entry price. They are x86 chips that run Windows or Linux, come in laptops as well as mini desktops, and Strix Halo systems have been cheaper than GB10 systems at the same memory size.
- GB10 wins on software maturity and scale-out. CUDA, vLLM, SGLang and NVFP4 work out of the box, and each unit has a 200 Gb/s ConnectX-7 network port for multi-unit clusters.
- Every platform has a weak spot. GB10: an unexplained power-off under some long-prompt loads, which a GPU clock lock stopped on our pod. Strix Halo: slower long-context prefill and a less mature GPU software stack. Gorgon Halo: not shipping yet, no independent benchmarks, and higher reported system prices.
The three platforms at a glance
These lists stick to what the vendors confirm on their own spec pages, plus the few details our own units report. Everything reported or rumored is labeled as such.
NVIDIA GB10 (DGX Spark, MSI EdgeXpert and other GB10 systems)
- CPU: 20 Arm cores (10 Cortex-X925 and 10 Cortex-A725).
- GPU: Blackwell architecture with fifth-generation Tensor Cores; NVIDIA rates it at up to 1 petaFLOP of FP4 compute with sparsity.
- Memory: 128 GB of LPDDR5X unified memory on a 256-bit interface, 273 GB/s. Our units report 121.7 GiB usable to the operating system.
- Networking: 10 GbE plus a ConnectX-7 NIC at 200 Gb/s.
- Power: a 240 W external power supply; NVIDIA lists the GB10 chip at 140 W TDP.
- Software: DGX OS (Ubuntu-based) with the NVIDIA CUDA stack.
- Status: shipping since October 2025 from NVIDIA and partners including MSI, ASUS, Dell, Lenovo, Gigabyte, Acer and HP.
We cover the chip itself on our DGX Spark hardware page and the memory design in Grace Blackwell unified memory explained.
AMD Strix Halo (Ryzen AI Max 300 series)
- CPU: up to 16 Zen 5 cores and 32 threads (Ryzen AI Max+ 395).
- GPU: Radeon 8060S, 40 RDNA 3.5 compute units at up to 2,900 MHz.
- NPU: XDNA 2, up to 50 TOPS.
- Memory: 256-bit LPDDR5X-8000, up to 128 GB, which works out to 256 GB/s theoretical bandwidth.
- GPU memory: up to 96 GB can be assigned to the GPU on Windows, and AMD documents raising that to about 120 GB on Linux.
- Power: configurable from 45 W to 120 W, set by each system maker.
- Status: announced at CES in January 2025 and now sold in laptops (such as the HP ZBook Ultra G1a), mini desktops (such as the Framework Desktop and GMKtec EVO-X2) and, since July 2026, AMD's own Ryzen AI Halo developer box.
Our Strix Halo AI processor guide covers the full lineup.
AMD Gorgon Halo (Ryzen AI Max PRO 400 series)
- CPU: up to 16 Zen 5 cores and 32 threads at up to 5.2 GHz (Ryzen AI Max+ PRO 495).
- GPU: Radeon 8065S, 40 RDNA 3.5 compute units at up to 3,000 MHz; the PRO 490 and PRO 485 use a 32-unit Radeon 8050S.
- NPU: XDNA 2, up to 55 TOPS on the PRO 495.
- Memory: 256-bit LPDDR5X-8533, up to 192 GB. That works out to about 273 GB/s theoretical bandwidth, the same figure NVIDIA quotes for GB10.
- GPU memory: AMD says up to 160 GB can be dedicated to graphics.
- Power: configurable from 45 W to 120 W.
- Status: announced May 20, 2026; see the next section for what is and is not available yet.
What Gorgon Halo is, and what is still unconfirmed
Gorgon Halo was a codename in leaks until AMD announced it in May, so it is worth separating the facts from the noise. Here is what we could verify on September 27, 2026, sorted by how solid the source is.
Confirmed by AMD
- AMD's product page for the Ryzen AI Max+ PRO 495 lists its former codename as Gorgon Halo, with the Zen 5 architecture, 192 GB maximum memory and LPDDR5X-8533.
- AMD announced the Ryzen AI Max PRO 400 series on May 20, 2026, describing Zen 5 CPU cores, RDNA 3.5 graphics, an XDNA 2 NPU, 192 GB of system memory and 160 GB of graphics memory.
- At its Advancing AI event on July 23, 2026, AMD said systems with the series will be available in its Ryzen AI Halo developer platform and in OEM systems "later this year".
- ROCm 7.14, released in July 2026, brings full ROCm enablement to the PRO 495, 490 and 485.
- The models AMD has announced are all PRO parts. As of September 27, 2026 we found no announced consumer Ryzen AI Max 400 part, and press coverage describes the consumer version as undecided.
Reported by reputable outlets, not yet confirmed by AMD
- HP ZBook Ultra G3a: VideoCardz reported on September 22, 2026 that HP's own pricing tool showed the PRO 495 laptop at $5,999 with 128 GB and $7,449 with 192 GB, ahead of an October release.
- Memory speed may vary by system: VideoCardz also reported that HP's product specification lists its 128 GB and 192 GB configurations at up to 8000 MT/s, while a reviewer's pre-production unit ran at 8533. At 8000 MT/s the bandwidth would be 256 GB/s, the same as Strix Halo. Check the memory speed of the exact system you buy.
- Lenovo ThinkCentre X Ultra: reported as a 1.6-liter desktop with the PRO 495, up to 128 GB (not 192 GB), from 3,100 euros in November 2026.
- Framework Desktop: Framework lists a 192 GB PRO 495 model as coming soon, without a price; Notebookcheck reported that Framework expects a substantial price step over the 128 GB model.
- No independent benchmarks yet. We found no published LLM results from production Gorgon Halo hardware.
Rumored: Medusa Halo
Medusa Halo is the name attached to the generation after Gorgon Halo. AMD's public roadmap from November 2025 placed "Medusa" products with Zen 6 in 2027. Leaks describe more CPU cores, RDNA 5 graphics and LPDDR6 memory, which would raise bandwidth well above today's class. AMD has not confirmed any Medusa Halo specification, so treat those numbers as rumors and do not plan a purchase around them.
The practical reading: Gorgon Halo is a capacity and clock refresh of Strix Halo. The jump from 128 GB to 192 GB matters if you want to hold a larger model or several models at once. The bandwidth gain, about 7 percent at 8533 MT/s, is small, and the GPU compute is the same generation, so expect Gorgon Halo to behave like a slightly faster Strix Halo with more room, not like a GB10.
Why DGX Spark vs Strix Halo is closer than the price suggests
When a model generates text, it reads its active weights from memory for every token. On these unified-memory machines, that read is the bottleneck, so tokens per second for one user roughly equals memory bandwidth divided by the bytes read per token. A dense 27B model at 4-bit reads about 15 to 17 GB per token, so any 256 to 273 GB/s machine lands near 10 to 15 tokens per second. A mixture-of-experts model that activates only 3 billion parameters per token reads a small fraction of that and runs several times faster on the same hardware.
Rated bandwidth is not delivered bandwidth, so we measured it. On September 27, 2026 we ran the same PyTorch GPU memory test on both of the machines in our same-day comparison. A freshly rebooted DGX Spark read its memory at 258.8 GB/s, 95 percent of the 273 GB/s rating. This unit and the other seven in our GB10 pod read 262 to 263 GB/s on fresh boots the day before, so 259 is a slightly low reading for it. Our Strix Halo laptop read at 234 to 235 GB/s in two runs, 91 to 92 percent of its 256 GB/s rating. A copy test gave 238.5 GB/s on the DGX Spark and 207 to 209 GB/s on the laptop. On the read and copy tests that is a gap of about 10 to 15 percent, wider than the 7 percent the ratings suggest; a third test (triad) narrowed it to 2 to 4 percent. GB10 has one catch of its own: after an inference engine has been launched and stopped, the next engine's buffers land in fragmented memory and read at 238 to 242 GB/s, and on our pod a reboot before launching restored the full figure and raised decode speed by 4 to 5 percent.
The takeaway for buyers: for one person chatting with a model, these machines are in the same class, and model choice matters more than the badge. For long prompts and many simultaneous users, compute matters, and that is a different story.
Our measurements: DGX Spark vs Strix Halo, same build, same files
The fairest comparison runs the same software build, the same model files and the same settings on each machine, on the same day. We did that on September 27, 2026 with two machines. The first was our HP ZBook Ultra G1a laptop (Ryzen AI Max+ PRO 395, 128 GB, Windows 11, HP's "HP Optimized" power plan, plugged in, 32 GB of memory dedicated to graphics). The second was one DGX Spark (DGX OS on Ubuntu 24.04, rebooted immediately before each llama.cpp test, with the GPU clock lock described in the reliability section). Both ran llama.cpp build b11213 from the project's official release packages, CUDA on the DGX Spark and both Vulkan and ROCm on the laptop, with byte-identical model files. We also reran our April 2026 Ollama test on both with the same Ollama version, 0.34.0, the same five model files as in April and the same prompts.
llama.cpp, same build: generation and prompt processing
We used llama-bench with every layer on the GPU and flash attention on. Each test processes a 512-token prompt and generates 128 tokens, first with an empty context and then with 8,192 and 32,768 tokens already in the context. Results are the mean of three repetitions in tokens per second, DGX Spark first and the Strix Halo laptop on Vulkan second (ROCm results follow):
- Qwen3.6-35B-A3B (mixture of experts, 3B active), Q4_K_M, 22.1 GB: generation 69.5 vs 59.4 with an empty context, 66.5 vs 56.4 at 8K and 58.5 vs 49.4 at 32K. Prompt processing 2,323 vs 1,313, then 2,165 vs 1,028 at 8K and 1,907 vs 638 at 32K.
- gpt-oss-120b (mixture of experts), MXFP4, 63.4 GB: generation 59.5 vs 44.7 with an empty context and 55.1 vs 40.7 at 8K. Prompt processing 1,868 vs 628, then 1,732 vs 450 at 8K. At 32K the DGX Spark held 45.5 tokens per second of generation and 1,381 of prompt processing; the laptop result at 32K is explained below.
Comparing the DGX Spark with the laptop's better AMD backend for each test, the DGX Spark generated text 17 to 33 percent faster in a short conversation and up to 41 percent faster with a long one. Prompt processing is a different story. The DGX Spark read prompts 1.8 to 2.7 times as fast with an empty context, and 2.1 to 3.8 times as fast once the context held 8,000 to 32,000 tokens. That gap, not generation speed, is what you feel with retrieval, coding agents and long documents.
One laptop result needs a warning. With gpt-oss-120b and 32,768 tokens of context, the laptop's first prompt-processing pass ran at 242 tokens per second, the next two fell to 18 and 16, and generation dropped to 4.7 tokens per second. We saw the same pattern in two separate runs, the second with nothing else running on the machine. The same test on the same laptop with ROCm did not drop (see below), and the smaller Qwen model showed no such collapse at 32K on either backend, so in our tests the problem was limited to the Vulkan path with the larger model. This laptop dedicates 32 GB to graphics, so most of the 63 GB model lives in shared system memory; our reading is that the model plus a long context overran what the Vulkan path could keep resident. We did not test a larger dedicated-memory setting (AMD allows up to 96 GB on Windows). If you plan to run 120B-class models with long contexts on a Strix Halo machine under Windows, test your exact configuration before you commit.
On the laptop we also ran the same build's ROCm package for Windows, which needed AMD's ROCm 7.13 libraries for this GPU installed alongside it. ROCm generated 8 to 11 percent more slowly than Vulkan, but it processed prompts faster once the context was long (760 against 638 tokens per second for Qwen at 32K, and 587 against 450 for gpt-oss-120b at 8K), and it did not show the Vulkan drop: gpt-oss-120b at 32K held 359 tokens per second of prompt processing and 32.3 of generation. On Windows, ROCm is the safer choice for large models with long contexts, and Vulkan the faster one for generation.
Ollama, same version: our April test rerun
Ollama 0.34.0 on both machines, the same five model files we used in April (identical digests), temperature 0, a fixed seed and four prompt sizes from a short answer to a prompt of about 4,300 to 4,400 tokens. The figure is the median generation speed across the four, DGX Spark first and laptop second:
- Qwen3.6 35B (mixture of experts, about 3B active), 4-bit: 74.5 vs 54.4.
- Gemma 4 26B (mixture of experts), 4-bit: 66.1 vs 51.8.
- Qwen3.6 27B (dense), 4-bit: 12.6 vs 11.4.
- Gemma 4 31B (dense), 4-bit: 10.5 vs 8.8.
- Qwen2.5 72B (dense), 4-bit: 4.6 vs 4.0.
On dense models the gap was smallest, as the bandwidth math predicts: the DGX Spark led by 11 to 19 percent, close to what its 10 to 15 percent higher measured bandwidth suggests. On the two mixture-of-experts models it led by 28 to 37 percent. On the longest prompt, the DGX Spark processed the input 2.3 to 5.2 times as fast. Two lessons about software also stand out. The same model files ran much faster than in April on both platforms after driver, firmware and Ollama updates (our DGX Spark result on Qwen3.6 35B went from 56 to 74.5 tokens per second, on a different unit of the same model; the laptop, which ran Linux in April and Windows now, went from 29 to 54.4), so an old benchmark can understate either platform. And Ollama on the laptop chose AMD's ROCm backend, while llama.cpp on Vulkan generated faster on the same Qwen3.6 35B model, 59.4 against 54.4 tokens per second, although the two tests are not built the same way.
A laptop is not a desktop. In our April test, our Linux Strix Halo desktop ran 7 to 48 percent ahead of this laptop (then also on Linux) on the same five models, which we attribute mainly to the desktop's higher power limit. Expect a Strix Halo mini desktop to land closer to the DGX Spark than our laptop does.
Each platform on its best engine
Ollama and llama.cpp are convenient, but neither is the fastest way to serve many users on GB10, so we also tested each platform on the software that suits it best.
- Strix Halo desktop, llama.cpp llama-bench (May 2026, Linux): gpt-oss-20b generated 76.1 tokens per second on the Vulkan RADV driver and 69.2 on ROCm 7.2.3, while ROCm processed prompts faster (1,712 vs 1,476 tokens per second at 512 tokens).
- GB10, vLLM with NVFP4 (September 2026): NVIDIA's Nemotron-3.5-Lightning-30B-A3B generated 84 to 90 tokens per second for one user with speculative decoding, and Qwen3.8-27B in NVFP4 generated 23.6 tokens per second on prose and 31.4 on code for one user.
So for one user, a well-tuned Strix Halo is competitive. For one user, the gap between platforms is smaller than the gap between engines and models.
Prompt processing and long context
Prefill, the step where the model reads your prompt before answering, is where GB10's extra compute shows. It matters for retrieval-augmented generation, coding agents and document review, where prompts run to tens of thousands of tokens and answers are short.
- Our same-build llama.cpp test: as above, the DGX Spark read prompts 1.8 to 3.8 times as fast as the laptop on its better backend, and the gap widened as the context grew. On the laptop itself, ROCm processed prompts up to 30 percent faster than Vulkan at long contexts, and about 4 times as fast in the one case where Vulkan collapsed.
- Our GB10 serving measurement: one unit running Nemotron-3.5-Lightning in NVFP4 on vLLM processed a 32,000-token prompt at about 6,100 to 6,260 tokens per second and a 131,000-token prompt at about 4,450.
- Third-party, Strix Halo on Linux: we did not test a Linux Strix Halo desktop with ROCm this time. kyuz0's published Strix Halo toolbox results for gpt-oss-120b at a 32,000-token context show 589 tokens per second of prompt processing on ROCm 7.2.3 and 308 on Vulkan (May 2026 build, 2,048-token prompts), against 1,381 on our DGX Spark with 512-token prompts. Different prompt sizes and builds, so treat the ratio as indicative.
- Third-party, serving: StorageReview's July 2026 review found AMD's Ryzen AI Halo (Strix Halo) trailing the DGX Spark 2 to 4 times in most vLLM serving tests and 8.8 times on a prefill-heavy gpt-oss-120b test. Tom's Hardware likewise found the Strix Halo box's time to first token falling well behind a GB10 system as context length grew.
Many users at once
If one machine will serve a team, batching matters more than single-user speed. vLLM on GB10 batches requests efficiently: in our September runs, one unit served Nemotron-3.5-Lightning to 32 users at about 590 to 620 tokens per second in total and to 64 users at about 765 to 805, and Qwen3.8-27B to 32 users at 303 tokens per second in total. On the Strix Halo laptop, llama.cpp with four simultaneous requests delivered 47.1 tokens per second in total, less than a single user got alone. vLLM does run on ROCm, but on our Strix Halo desktop in May 2026 a ROCm vLLM build took about 13 seconds per request where llama.cpp on Vulkan took 1.2. AMD's ROCm 7.14.1 release notes still list slow vLLM FP16 decode at batch 8 or more with older PyTorch versions as a known issue. Our conclusion: Strix Halo is a strong single-user machine; GB10 is the better small team server.
Software ecosystem: CUDA vs ROCm, Vulkan and Lemonade
GB10: CUDA, vLLM, SGLang and NVFP4
GB10 runs the same CUDA stack as NVIDIA's data center GPUs, so most inference and training tools work without porting. We run vLLM, SGLang, llama.cpp and Ollama on our pod, mostly from NVIDIA's and the projects' own ARM64 container images. NVFP4, NVIDIA's 4-bit floating point format with hardware support in Blackwell, is widely published for GB10, including by NVIDIA, and it is what lets a 30B-class model serve dozens of users on one unit. TensorRT-LLM also supports the platform; we have not benchmarked it. The caveats: the CPU is Arm, so some x86-only tools and containers need ARM64 builds, and driver, kernel and firmware updates have changed performance more than once this year. Our DGX Spark firmware update report documents one such update across all eight units. llama.cpp's Vulkan backend is not the right choice on GB10: in May 2026 CUDA was 2.3 to 4.2 times faster than Vulkan on the same unit and models.
Strix Halo and Gorgon Halo: ROCm, Vulkan, llama.cpp and Lemonade
AMD's software story has improved quickly. ROCm now officially supports the Strix Halo GPU (gfx1151), and ROCm 7.14 extends the same support to the Gorgon Halo parts, which use the same GPU target. Popular ways to run LLMs on these chips are llama.cpp, either directly or inside LM Studio or Ollama, and Lemonade, a community-built open-source server with optimizations from AMD engineers that exposes OpenAI-compatible and Ollama-compatible APIs. The choice of backend matters more than on NVIDIA: in our tests Vulkan generated tokens about 8 to 30 percent faster than ROCm, while ROCm processed prompts faster, by 16 percent on our Linux desktop in May and by up to 30 percent at long contexts on our Windows laptop in September, where it was also the only backend that kept gpt-oss-120b fast at a 32,000-token context. Serving engines built for batching, such as vLLM, are less mature on these chips than on CUDA. Community projects such as kyuz0's Strix Halo toolboxes publish ready-made containers and benchmark results for each backend, which saves a lot of trial and error.
Operating systems and drivers
- Windows: Strix Halo and Gorgon Halo run Windows 11 natively, and LM Studio, Ollama and llama.cpp all have Windows builds that use the GPU. On our Windows laptop, the GPU was not available inside WSL2 in our setup, so a WSL2 run fell back to the CPU at 15.5 to 16.1 tokens per second against about 43 on the Windows side. Windows' "High performance" power plan also cut GPU inference by 5 to 15 percent on the laptop, because the CPU and GPU share one power budget; HP's default power plan was faster.
- Linux: both AMD chips run mainstream Linux distributions with a recent kernel. GB10 ships with DGX OS, an Ubuntu-based distribution maintained by NVIDIA, and does not run Windows.
- Laptops: only the AMD chips come in laptops. A GB10 is a small desktop.
Clustering: 200G ConnectX-7 vs Ethernet
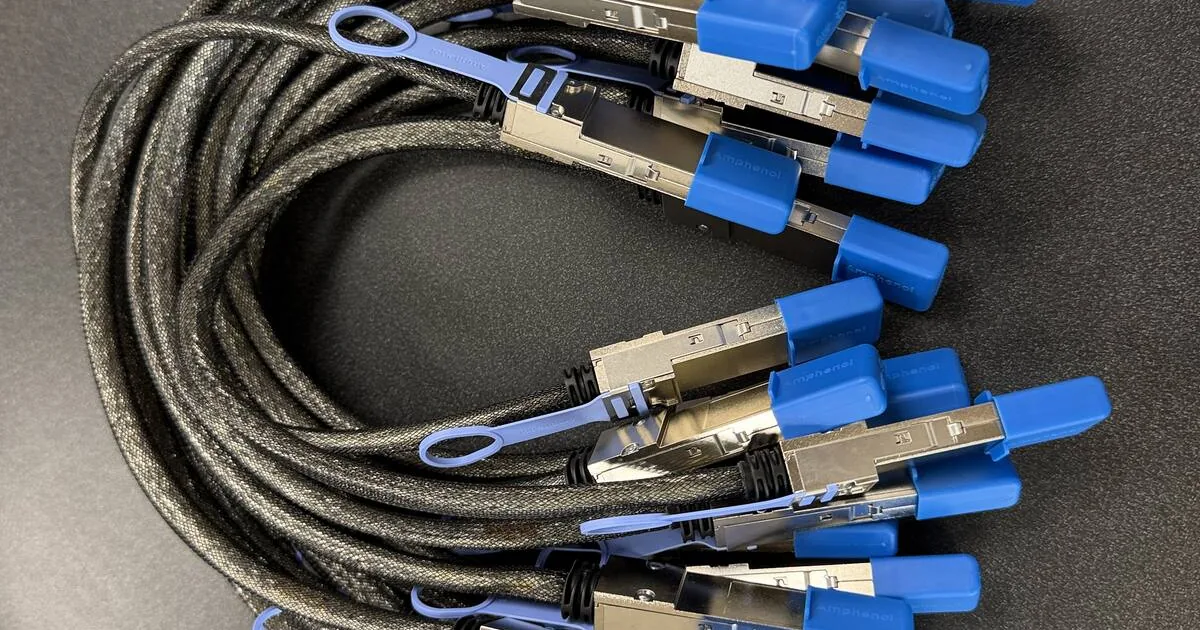
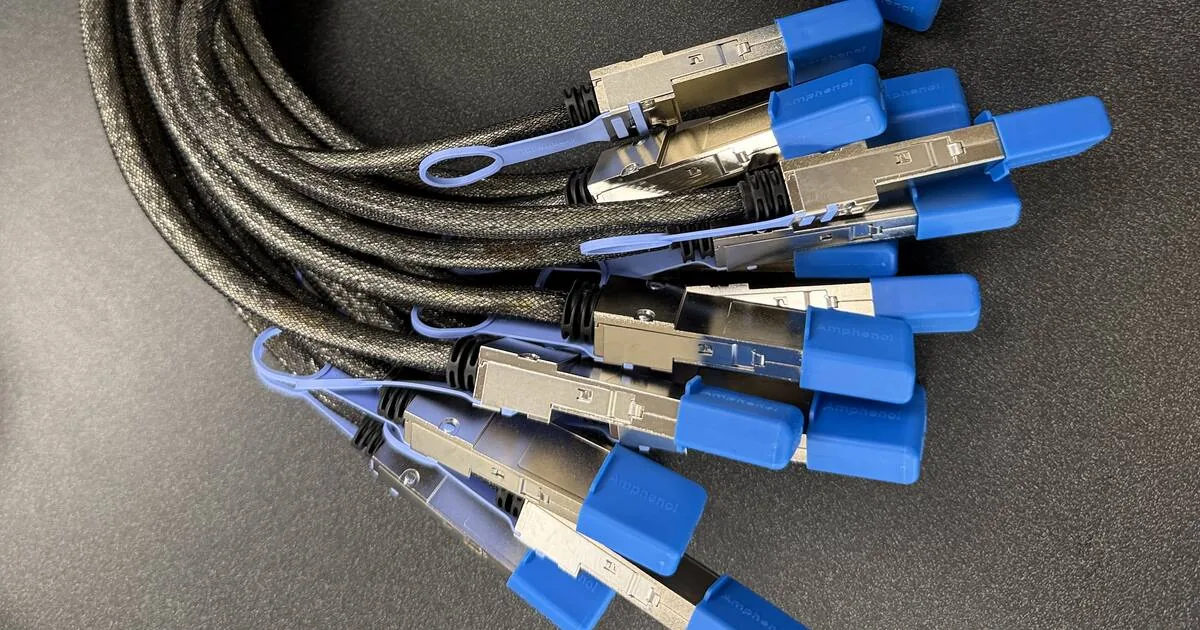
When a model is too large for one machine, you split it across several. This is GB10's clearest hardware advantage. Every GB10 system has a ConnectX-7 port rated at 200 Gb/s with RDMA, and NVIDIA supports linking units for models up to about 700 billion parameters. We run tensor-parallel jobs across two, four and eight units over a 200G switch; our post from two Sparks to a switched fabric covers the build, and our DGX Spark cluster cable guide covers the parts.
Strix Halo and Gorgon Halo can cluster too, but over ordinary Ethernet. AMD's own guides show four Framework Desktops running Kimi K2.5, a one-trillion-parameter model, over 5 Gb/s Ethernet and two Ryzen AI Halo boxes on a 10 GbE switch, both using llama.cpp's RPC mode, which splits the model's layers across machines. That works for fitting a very large model, but the links in those guides run at 5 to 10 Gb/s against GB10's 200 Gb/s with RDMA, and a 10 GbE network adds to the cost. Reports for the Lenovo ThinkCentre X Ultra mention 10 GbE and clusters of up to four units. If clustering is central to your plan, GB10 is the more proven path today.
Reliability: what we learned running eight GB10 units
A fair comparison includes the problems. In September 2026 several units in our GB10 pod powered off without warning at the start of very long prompts, most often when the unit was already hot. The operating system logged nothing. We traced it with external telemetry and found that locking the GPU clock with nvidia-smi -lgc 300,2200 at boot stopped it: with the lock on seven units, 66 long-prompt starts under full load produced no power-offs. The cost was 1 to 3 percent of single-user decode speed on our diagnosis unit and nothing at 32 users. NVIDIA's forum moderator has described capping the GPU clock as a community mitigation while shutdowns reported by some GB10 users are investigated. The full write-up is in DGX Spark shutdown under load: our 8-unit GB10 diagnosis.
We have not seen an equivalent problem on our Strix Halo machines, but we have also run them far less hard: no multi-hour, pod-wide stress runs. Our AMD issues were software ones, such as backend choice, an outdated-driver warning from Ollama on Windows that did not stop it from using the GPU, and speculative-decoding runs of Gemma 4 that produced degenerate, repetitive output at high speed, which we caught by checking output quality alongside speed.
Price and affordability
Memory shortages pushed the prices of the DGX Spark and the Framework Desktop up in 2026, so the numbers below are list prices from the maker where one is published, dated, and labeled. Prices change often and street prices vary with market conditions; check current pricing before you budget.
- NVIDIA DGX Spark Founders Edition: $4,699 MSRP since NVIDIA raised it from $3,999 in February 2026, citing memory supply constraints. Partner GB10 systems set their own prices.
- AMD Ryzen AI Halo (Strix Halo, 128 GB): $3,999 retail price per AMD as of May 2026, sold through Micro Center.
- Framework Desktop with Ryzen AI Max+ 395, 128 GB: $1,999 when announced in February 2025; Notebookcheck reported Framework's price at $3,449 in July 2026 after memory-driven increases.
- Gorgon Halo systems: AMD has not published pricing. The reported HP ZBook Ultra G3a prices are $5,999 with 128 GB and $7,449 with 192 GB, and the reported Lenovo ThinkCentre X Ultra starts at 3,100 euros; both are pre-release figures.
What the money buys differs. For a single user running mixture-of-experts models, a Strix Halo mini desktop delivers most of a GB10's speed for less money, and AMD itself markets a tokens-per-dollar advantage over the DGX Spark (a vendor claim, based on AMD's own tests). For a team server or long-prompt workloads, GB10's throughput per dollar is higher, because a single unit serves hundreds of tokens per second in total. At the wall, our DGX Spark drew about 45 to 60 W with no model loaded and 130 to 158 W while generating in the September 27 tests (outlet readings every 30 seconds), in line with the 127 to 148 W we measured earlier while it served Qwen3.8-27B. We could not measure wall power on the Strix Halo laptop: it is not on a metered outlet, and a laptop charger's draw mixes battery charging with compute, so we do not estimate it. AMD lets system makers configure the chip between 45 and 120 W.
Strengths and weaknesses of each platform
NVIDIA GB10 (DGX Spark and partner systems)
- Strength: CUDA and the full NVIDIA software stack, including vLLM, SGLang and NVFP4 models, with the fewest surprises when porting work to or from data center GPUs.
- Strength: the fastest prompt processing and multi-user serving of the platforms tested, by a wide margin.
- Strength: a 200 Gb/s ConnectX-7 port on every unit for real multi-unit clusters.
- Weakness: a higher price than Strix Halo systems at 128 GB, after NVIDIA's 2026 increase to $4,699.
- Weakness: Arm CPU and DGX OS only, so no Windows and some x86 tools need ARM64 builds.
- Weakness: the power-off under some long-prompt loads that we and other owners have seen; a clock lock is a workaround, not a fix.
- Weakness: single-user speed on dense models is only 11 to 19 percent ahead of a Strix Halo laptop in our test, because the bandwidth is similar.
AMD Strix Halo (Ryzen AI Max 300)
- Strength: a lower price than a DGX Spark at 128 GB (up to 96 GB usable by the GPU on Windows and about 120 GB on Linux), in the widest range of form factors, including laptops.
- Strength: x86, so Windows and Linux both work, and it doubles as a fast general-purpose workstation; StorageReview found it ahead of the DGX Spark on CPU work.
- Strength: single-user generation 10 to 16 percent behind a DGX Spark on dense models and 15 to 29 percent behind on mixture-of-experts models, in our same-day test of a Strix Halo laptop; a desktop with a higher power limit should do better.
- Weakness: much slower prompt processing at long context, which hurts retrieval and coding-agent workloads.
- Weakness: weak multi-user serving today; llama.cpp does not batch the way vLLM on CUDA does, and vLLM on ROCm is still maturing.
- Weakness: more tuning work: backend choice, GPU memory settings and power plans all change results noticeably.
- Weakness: clustering only over ordinary Ethernet.
AMD Gorgon Halo (Ryzen AI Max PRO 400)
- Strength: up to 192 GB, the most memory of the three, with up to 160 GB usable by the GPU per AMD.
- Strength: 273 GB/s theoretical bandwidth at LPDDR5X-8533, matching GB10 on paper, plus the same x86 and Windows flexibility as Strix Halo.
- Strength: ROCm support from day one, since it shares Strix Halo's GPU target.
- Weakness: not shipping as of September 27, 2026, with no independent benchmarks.
- Weakness: the same GPU compute class as Strix Halo, so the prompt-processing and serving gaps against GB10 remain.
- Weakness: only PRO models, and the reported system prices are well above Strix Halo and, for 192 GB, above a DGX Spark.
- Weakness: some systems are reported to run the memory at 8000 MT/s, which would give no bandwidth gain over Strix Halo.
Which one fits you: the best hardware for local LLM work
- A developer who wants a private model on a laptop: Strix Halo now, or Gorgon Halo if you need 192 GB and can wait. No GB10 laptop exists.
- A single user on a desk, mostly chat and writing, on a budget: a Strix Halo mini desktop running a mixture-of-experts model on llama.cpp. It is the most affordable DGX Spark alternative for this job.
- A small team sharing one model, or long documents and coding agents: GB10. The prompt-processing and batching advantage is large enough to matter every day.
- Work that must move to data center GPUs later: GB10, because the CUDA code, containers and NVFP4 models carry over.
- Models too large for one box: a GB10 cluster over its 200G ports, or an Ethernet cluster of AMD systems if you can accept lower speed for lower cost.
- A Windows shop: Strix Halo or Gorgon Halo; GB10 does not run Windows.
- High-throughput production inference or training: none of the three. A workstation or server with discrete GPUs is the right tool; see our RTX PRO 6000 vs GB10 benchmark and our AI inference workstations page.
For regulated organizations, the platform matters less than the deployment: where the machine sits, who can reach it, how models and data are logged and backed up, and how it fits your security controls. Our private LLM and on-premise AI services cover that side.
Related reading
- DGX Spark Cluster Cable (QSFP112 400G DAC)
- Mac Studio M5 Ultra vs NVIDIA DGX Spark for Local AI
- DGX Spark Firmware Update: What We Learned on 8 GB10 Units
- DGX Spark Shutdown Under Load: Our 8-Unit GB10 Diagnosis
- DGX Spark Cluster: 4 to 8 Nodes, Switch vs Ring
FAQ
Is the DGX Spark faster than Strix Halo?
For one user generating text, somewhat: in our same-day test with identical software and model files, a DGX Spark generated 11 to 19 percent faster than our Strix Halo laptop on dense models and 17 to 41 percent faster on mixture-of-experts models. For long prompts it is much faster: it read prompts 1.8 to 3.8 times as fast in the same test, and independent reviewers measured gaps of 2 to 8.8 times in vLLM serving tests.
Which is better, the DGX Spark or the AMD Ryzen AI Halo?
It depends on the job. The DGX Spark, at $4,699 MSRP, is better for teams, long prompts and CUDA work: in our tests a GB10 read prompts 1.8 to 3.8 times as fast as a Strix Halo machine and batches many users with vLLM. The Ryzen AI Halo, a Strix Halo system with the same 128 GB at $3,999 per AMD, costs less and runs Windows as well as Linux; on dense models our Strix Halo laptop was only 10 to 16 percent behind a DGX Spark for a single user. We have not tested AMD's Ryzen AI Halo box itself; our Strix Halo results come from an HP laptop and our lab desktops.
What is AMD Gorgon Halo?
Gorgon Halo is the former codename of the AMD Ryzen AI Max PRO 400 series, announced May 20, 2026. AMD confirms Zen 5 CPU cores, RDNA 3.5 graphics, LPDDR5X-8533 memory and up to 192 GB. It is a refresh of Strix Halo with more memory and higher clocks, and systems were announced for later in 2026.
Is Gorgon Halo faster than Strix Halo for LLMs?
Probably a little. Its memory is rated about 7 percent faster and its GPU clocks are higher, so single-user generation should improve slightly on systems that run the memory at 8533 MT/s. The bigger change is capacity, 192 GB instead of 128 GB. No independent LLM benchmarks of production Gorgon Halo systems were available as of September 27, 2026.
Does Gorgon Halo have as much memory bandwidth as the DGX Spark?
On paper, yes: LPDDR5X-8533 on a 256-bit bus works out to about 273 GB/s, the figure NVIDIA quotes for GB10. Some systems are reported to run their memory at 8000 MT/s, which gives 256 GB/s, the same as Strix Halo.
Can Strix Halo run a 120B model?
Yes, if it is a mixture-of-experts model at 4-bit. Our Strix Halo laptop ran gpt-oss-120b entirely on its GPU under Windows at 44.7 tokens per second with an empty context and 40.7 with 8,192 tokens of context, against 59.5 and 55.1 on a DGX Spark with the same llama.cpp build. At a 32,768-token context the laptop, which dedicates 32 GB to graphics, slowed to under 5 tokens per second, so test long contexts on your exact configuration. kyuz0's published Linux results for a Framework Desktop are 52 to 57 (third-party). A dense 72B model at 4-bit ran at 4.0 tokens per second on the laptop and 4.6 on the DGX Spark.
Can you cluster Strix Halo machines like DGX Sparks?
Yes, but over Ethernet. AMD documents llama.cpp RPC clusters of Strix Halo systems over 5 and 10 GbE, which lets several machines hold a very large model. GB10 systems have 200 Gb/s ConnectX-7 ports with RDMA, which is much faster between units.
What is the best DGX Spark alternative for local LLMs?
For a single user on a budget, a Strix Halo mini desktop is the closest alternative, with similar memory and similar single-user speed. For Windows or a laptop, Strix Halo or Gorgon Halo. For team serving, there is no cheaper equivalent to a GB10 with the same software stack.
Should the DGX Spark power-off issue stop me from buying one?
Not by itself, in our experience. The power-offs we saw came at the start of very long prompts on hot units, and a GPU clock lock at boot stopped them across 66 long-prompt starts under full load, at a cost of 1 to 3 percent of single-user speed on our diagnosis unit and more on another unit. It is a workaround until NVIDIA ships a platform fix, so plan to apply it.
What is the AMD equivalent to the DGX Spark?
A Strix Halo system with the Ryzen AI Max+ 395 and 128 GB of memory, such as AMD's own Ryzen AI Halo, the Framework Desktop or the HP ZBook Ultra G1a laptop. Like the DGX Spark, it shares one pool of LPDDR5X memory between the CPU and GPU on a 256-bit bus. Gorgon Halo, the Ryzen AI Max PRO 400 series, is its successor with up to 192 GB.
What are the downsides of the NVIDIA DGX Spark?
A higher price than Strix Halo systems with the same 128 GB, an Arm CPU with DGX OS instead of Windows, only an 11 to 19 percent single-user speed advantage on dense models in our tests because its memory bandwidth is in the same class, and the power-off under some long-prompt loads that we and other owners have seen, which a GPU clock lock works around.
Can the DGX Spark run Windows?
NVIDIA ships the DGX Spark with DGX OS, an Ubuntu-based Linux distribution, on an Arm CPU, and we know of no supported Windows option for it. If your team needs Windows on the same machine, a Strix Halo or Gorgon Halo system runs Windows 11 natively.
What comes after Strix Halo?
Gorgon Halo, sold as the Ryzen AI Max PRO 400 series, announced by AMD on May 20, 2026, with systems due later in 2026. After that, AMD's roadmap places Zen 6 "Medusa" products in 2027; the Medusa Halo specifications that circulate online are rumors that AMD has not confirmed.
When will Gorgon Halo systems be available?
AMD said in July 2026 that systems will be available in its Ryzen AI Halo developer platform and from PC makers later this year. Reported dates are October 2026 for HP's ZBook Ultra G3a and November 2026 for Lenovo's ThinkCentre X Ultra; neither was shipping to customers on September 27, 2026.
Get help choosing and deploying local AI hardware
Petronella Technology Group, Inc. tests these platforms on our own bench before we recommend them, and we design, deploy and secure private AI systems for organizations that cannot send their data to a public cloud. If you are choosing between a DGX Spark, a Strix Halo or Gorgon Halo system, or a GPU workstation, we will size the hardware to your models, users and security requirements, and we can deliver it as a managed private LLM deployment or, for larger needs, a private AI cluster. We publish our benchmark data, weaknesses included.
Not sure which platform fits your workload? Talk to Petronella Technology Group, Inc.
Free, practical, and specific to regulated environments. We will email it to you.
No spam. Unsubscribe anytime.