A private AI appliance is a self-contained hardware stack that runs open-weight AI models on your premises, keeping regulated data off public cloud APIs.
This guide is for security leaders, compliance officers, and IT directors at defense contractors, healthcare providers, and other regulated firms evaluating on-premises AI. It covers the hardware requirements, the compliance frameworks that drive the need for isolation, and the specific steps to validate a deployment before it touches production data.
Key Takeaways
- A 7B parameter model runs on a single NVIDIA A100 or H100 GPU, while larger models require 2-4 GPUs.
- At 500K+ tokens per day, private deployment breaks even within 6-12 months compared to API spend.
- The deployment process requires defining the data boundary, sizing hardware, isolating the network, and mapping controls to frameworks like CMMC and HIPAA.
- Open-weight model families such as Llama 3.1, Mistral, Qwen 2.5, and Phi are supported and benchmarked against specific use cases.
- Encryption that is strong but not FIPS-validated does not meet NIST SP 800-171 requirements for protecting the confidentiality of CUI.
What a Private AI Appliance Is and Why It Exists
Many organizations assume that using a commercial AI API is the only way to access advanced language models. For firms handling sensitive data, this assumption creates a critical security gap. A private AI appliance is a dedicated hardware environment where inference occurs locally. The data never leaves the building. This architecture is not just a convenience; it is often a compliance requirement.
The Compliance Driver
Regulated industries face strict rules about where data can be processed. NIST SP 800-171 requires FIPS-validated cryptography to protect the confidentiality of Controlled Unclassified Information (CUI). If you send CUI to a public cloud API, you must ensure that the provider meets specific security baselines. DFARS 252.204-7012 requires a cloud service provider handling covered defense information to meet security requirements equivalent to the FedRAMP Moderate baseline. Commercial productivity tenants that have never been assessed against that baseline do not satisfy the clause.
Furthermore, the DoD CIO CMMC FAQ clarifies that encrypted CUI is still CUI. Even if the data is encrypted, if it resides in a cloud environment, it still needs FedRAMP Moderate or equivalency. A private AI appliance eliminates this dependency. By keeping the data and the model on your own network, you retain full control over the security posture without relying on a third party’s compliance status.
Hardware Realities
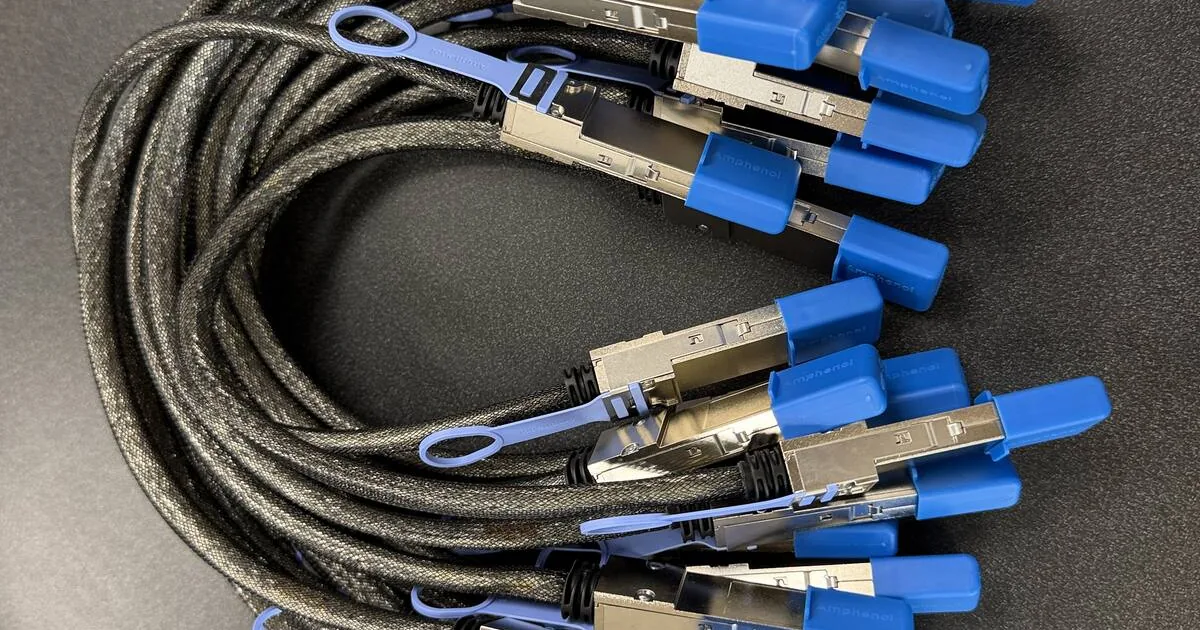
Running AI locally requires specific hardware. A 7B parameter model runs on a single NVIDIA A100 or H100 GPU. Larger models require 2-4 GPUs. For single-box inference workstations, sizing often revolves around RTX 5090, RTX 6000, or H200 class GPUs. For larger clusters, reference hardware includes GB10 Grace Blackwell nodes with 128GB unified memory each, clustered over a QSFP112 400G interconnect to pool 256GB for larger models. Understanding these hardware tiers is the first step in evaluating whether a private deployment is feasible for your specific model size and throughput needs.
How the Deployment Process Works
Deploying a private AI appliance is not simply plugging in a server. It is a structured process that aligns technical implementation with compliance obligations. Petronella Technology Group, Inc. uses a six-stage method to ensure that every deployment is secure and auditable from day one.
Stage One: Define the Data Boundary
The first step is to identify the frameworks that apply to your data. This includes CMMC Levels 1, 2, or 3, HIPAA, and DFARS 252.204-7012. You must map your data types to these frameworks to understand what controls are mandatory. For example, HIPAA requires a Risk Analysis under 45 CFR 164.308(a)(1)(ii)(A). There is no HHS-issued HIPAA certification, so your internal risk analysis is the primary document that proves compliance.
Stages Two and Three: Sizing and Isolation
Once the data boundary is clear, you size the GPU hardware based on the model family and expected token volume. At 500K+ tokens per day, private deployment breaks even within 6-12 months. At 5M+ tokens daily, costs are 60-80% less annually than equivalent API spend. After sizing, the cluster is isolated on a segmented VLAN or a full air gap. This network isolation is critical. It ensures that the AI environment cannot be accessed by unauthorized users or compromised by lateral movement from other parts of the network.
Stages Four and Five: Deployment and Hardening
Open-weight models are deployed on an inference stack that you control. Supported families include Llama 3.1, Mistral, Qwen 2.5, and Phi. Options are benchmarked against the client's use case before a recommendation is made. The hardening checklist covers network isolation, secrets handling, prompt and access logging, and egress control. Role-based access control, encryption at rest and in transit, and audit logging are layered onto the system. These logs are mapped to framework controls to ensure that every action is traceable.
Stage Six: Validation
Before production, the system is validated against the mapped controls. This step ensures that the technical implementation actually meets the compliance requirements defined in Stage One. Without this validation, you may have a working AI system, but you may not have a compliant one.
Evaluating Options and Providers
When evaluating a private AI appliance, you must look beyond the hardware specs. The value lies in the integration of security, compliance, and AI operations. A provider should be able to demonstrate how they handle the specific constraints of your industry.
Model Selection and Benchmarking
Not all open-weight models are created equal. Llama, Qwen, Mistral, and DeepSeek are common options. However, the best model depends on your specific use case. A provider should benchmark options against your data and performance requirements. For example, a model that excels at code generation may not be the best fit for medical record summarization. The selection process should be data-driven, not generic.
Operational Security and Auditability
In production, the AI must operate within strict guardrails. At Petronella Technology Group, Inc., the hybrid SOC runs ten-plus production AI agents on the enterprise private AI cluster. The AI never closes a ticket on its own and never touches production systems without human authorization. Every action is logged for CMMC and HIPAA audit. This human-in-the-loop approach is essential for maintaining trust and compliance. When evaluating a provider, ask how they ensure that the AI remains under human control and how they structure their logging to support audits.
| Component | Requirement | Compliance Mapping |
|---|---|---|
| Network Isolation | Segmented VLAN or full air gap | CMMC, HIPAA, DFARS 252.204-7012 |
| Encryption | FIPS-validated cryptography | NIST SP 800-171 |
| Access Control | Role-based access control | CMMC Level Two, HIPAA |
| Logging | Audit logging mapped to framework controls | CMMC, HIPAA |
Choosing a provider requires verifying their expertise in both AI and compliance. Petronella Technology Group, Inc. is a Cyber AB Registered Provider Organization, RPO #1449, and every engineer assigned to a defense client holds the CMMC-RP credential. This dual expertise ensures that the technical deployment aligns with the regulatory landscape. For more details on how to structure your own on-premises environment, review our guide on On-Premise AI: Keep Your Data Off the Cloud. If you are looking for a deeper technical dive into the hardware comparisons, see our analysis of RTX PRO 6000 Blackwell vs NVIDIA GB10 Grace Benchmark.
Aligning with NIST AI Risk Management Framework
As AI adoption accelerates, the risk landscape is evolving. Gartner projects $2.59T in AI spend in 2026, with agentic AI at $206.5B in 2026. With this growth comes increased scrutiny. NIST has developed the AI Risk Management Framework (AI RMF) to help organizations manage risks associated with AI. On July 26, 2024, NIST released NIST-AI-600-1, the Generative Artificial Intelligence Profile. This profile helps organizations identify unique risks posed by generative AI and proposes actions for risk management.
On April 7, 2026, NIST released a concept note for an AI RMF Profile on Trustworthy AI in Critical Infrastructure. This profile will guide critical infrastructure operators towards specific risk management practices to consider when engaging AI-enabled capabilities. For firms in regulated industries, aligning your private AI deployment with the AI RMF is a proactive step. It demonstrates that you are not just meeting the minimum compliance requirements, but are also managing the broader risks associated with AI adoption. The framework is intended for voluntary use, but for many organizations, it is becoming a de facto standard for assessing AI risk.
By integrating AI RMF practices into your private AI appliance deployment, you create a more strong security posture. This approach helps you identify potential risks early and implement controls that mitigate them. It also provides a clear audit trail that shows regulators and clients that you are taking AI risk management seriously. For a broader look at how AI fits into your overall security strategy, explore our AI solutions hub. To understand the specific compliance documentation required, visit our compliance resources.
Step-by-Step Implementation Plan
Deploying a private AI appliance is not a single purchase; it is a structured engineering effort. Based on our six-stage method, here is the sequence we follow to move from concept to production. This plan ensures that security and compliance are built into the architecture, not bolted on after the fact.
- Define the data boundary. Determine exactly which data classes will interact with the model. For defense contractors, this typically involves Controlled Unclassified Information (CUI). For healthcare providers, it involves Protected Health Information (PHI). You must also identify the specific regulatory frameworks that apply to this data, such as CMMC Levels 1, 2, or 3, HIPAA, or DFARS 252.204-7012. This step dictates the isolation level required later.
- Size the GPU hardware. Match the hardware to the model size. A 7B parameter model runs on a single NVIDIA A100 or H100 GPU. Larger models require 2-4 GPUs. If you are considering single-box inference workstations, look at RTX 5090, RTX 6000, or H200 class GPUs. For larger clusters, reference hardware includes GB10 Grace Blackwell nodes with 128GB unified memory each, clustered over a QSFP112 400G interconnect to pool 256GB for larger models.
- Isolate the cluster. Place the hardware on a segmented VLAN or implement a full air gap. Network isolation is critical. The blueprint hardening checklist covers network isolation, secrets handling, prompt and access logging, and egress control. If you are handling CUI, remember that NIST SP 800-171 requires FIPS-validated cryptography to protect confidentiality. Encryption that is strong but not validated does not meet the requirement as written.
- Deploy open-weight models. Install the inference stack you control. Supported open-weight model families include Llama 3.1, Mistral, Qwen 2.5, and Phi. Options are benchmarked against your specific use case before a recommendation is made. Other open-weight models named in our blueprint include Llama, Qwen, Mistral, and DeepSeek.
- Layer security controls. Implement role-based access control, encryption at rest and in transit, and audit logging. These logs must be mapped to your framework controls. For example, if you are under CMMC, your logging must support the assessment requirements. If you are under HIPAA, your access controls must satisfy the Security Rule at 45 CFR Part 164.
- Validate before production. Test the system against the specific controls of your framework before you go live. This validation step confirms that the private AI boundary is secure and compliant. Do not skip this step. It is the final gate before the system handles live data.
This process ensures that the appliance is not just a server with a GPU, but a compliant, secure component of your overall risk management strategy. You can learn more about the specific hardware benchmarks in our guide on RTX PRO 6000 Blackwell vs NVIDIA GB10 Grace Benchmark.
Common Mistakes in Assessments and How to Avoid Them
When we assess private AI deployments for clients, we see recurring errors that lead to compliance failures or security gaps. Avoiding these mistakes saves time and prevents costly rework.
- Assuming encryption equals compliance. A common error is assuming that because data is encrypted, it is compliant. NIST SP 800-171 requires FIPS-validated cryptography. If your encryption is not FIPS-validated, it does not meet the requirement. Similarly, DoD CIO CMMC FAQ clarifications state that encrypted CUI is still CUI, and encrypted CUI in a cloud still needs FedRAMP Moderate or equivalency. Do not assume that encryption alone solves the problem.
- Ignoring the cloud provider baseline. If you are using a cloud service provider to handle covered defense information, DFARS 252.204-7012 requires that provider to meet security requirements equivalent to the FedRAMP Moderate baseline. Commercial productivity tenants that have never been assessed against that baseline do not satisfy the clause. If you are using a private AI appliance on-premises, you avoid this specific cloud provider risk, but you must still ensure your on-premises environment meets the equivalent security standards.
- Underestimating the need for human oversight. In our own production environment, the AI never closes a ticket on its own and never touches production systems without human authorization. Every action is logged for CMMC and HIPAA audit. If you deploy an AI system that acts autonomously without human authorization, you create an audit trail gap. Ensure your system design includes human-in-the-loop controls for any action that impacts production systems.
- Skipping the risk analysis. The HIPAA Security Rule at 45 CFR Part 164 requires a Risk Analysis under 45 CFR 164.308(a)(1)(ii)(A). There is no HHS-issued HIPAA certification. Many organizations assume that buying a "compliant" appliance means they are done. They are not. You must perform your own risk analysis to determine how the AI system interacts with your specific PHI. The appliance is a tool; your risk analysis is the compliance mechanism.
- Not mapping logs to framework controls. Audit logging is essential, but it must be mapped to the specific controls of your framework. If you are under CMMC Level 2, which is the 110 security requirements of NIST SP 800-171 assessed under 32 CFR Part 170, your logs must support those specific assessments. If you are under CMMC Level 3, which layers selected NIST SP 800-172 requirements on top, your logs must support those additional controls. Generic logging is not enough.
These mistakes are avoidable with proper planning. For a deeper dive into the architectural choices for healthcare data, see our guide on HIPAA-Compliant Private LLMs: 5 Architectures.
How to Choose a Provider: The Questions to Ask
Choosing a provider for a private AI appliance is a significant decision. You need a partner who understands both the technology and the regulatory landscape. Here are the questions you should ask before you sign a contract.
- Do you have experience with our specific regulatory framework? Ask for examples of deployments in your industry. If you are a defense contractor, ask about CMMC Level 2 and Level 3 experience. If you are in healthcare, ask about HIPAA experience. The provider should be able to speak to the specific controls, such as NIST SP 800-171 or 45 CFR Part 164, in detail.
- What is your methodology for deployment? A reputable provider will have a defined process. Ask them to walk you through their steps. Do they define the data boundary first? Do they size the hardware based on the model? Do they isolate the cluster? Do they validate against framework controls before production? A vague answer is a red flag.
- How do you handle audit logging? Ask how their system logs actions and how those logs are mapped to framework controls. Ask if they provide tools to export logs for assessment. If they cannot answer this, they are not ready for a regulated environment.
- What is your support model? Ask if they offer managed services or if they just sell the hardware and software. If you need ongoing support, ask about their response times and their ability to provide 24/7 monitoring. In our own operations, we run a 24/7 AI-plus-human hybrid threat analysis stack. Ask if the provider offers similar capabilities.
- Can you provide references? Ask for references from clients in your industry. Speak to them. Ask about the provider's responsiveness, their technical expertise, and their ability to navigate compliance issues. A provider who is confident in their work will not hesitate to provide references.
- What is your pricing model? Ask for a clear breakdown of costs. Avoid providers who are vague about pricing. You want to understand the total cost of ownership, including hardware, software, and support. Remember that at 500K+ tokens per day, private deployment breaks even within 6-12 months. At 5M+ tokens daily, costs are 60-80% less annually than equivalent API spend. Use this to evaluate the provider's proposal.
These questions will help you identify a provider who is a true partner, not just a vendor. For more information on the services we offer, visit our private AI solutions page.
How Petronella Technology Group, Inc. Helps
Petronella Technology Group, Inc. designs, builds, and operates private AI clusters for regulated businesses end to end. We deliver the blueprint stack turnkey for regulated teams. Our approach is grounded in our own production experience. We run our own private AI cluster and 24/7 AI-plus-human hybrid threat analysis stack, which underpins managed detection and response for defense industrial base and healthcare clients that cannot send CUI or PHI to a public-cloud SOC.
In our hybrid SOC, we run ten-plus production AI agents on the enterprise private AI cluster. The AI never closes a ticket on its own, never touches production systems without human authorization, and every action is logged for CMMC and HIPAA audit. This is the same standard we apply to client deployments. We ensure that your private AI appliance is not just a tool, but a secure, compliant component of your overall risk management strategy.
We are a Cyber AB Registered Provider Organization, RPO #1449, and every engineer assigned to a defense client holds the CMMC-RP credential. This means that when you work with us on a defense project, you are working with engineers who are credentialed in the specific compliance framework you are under. We also provide ComplianceArmor®, our compliance documentation platform that automates SSP authoring, POA&M tracking, and evidence repository organization. This helps you manage the documentation burden that comes with private AI deployment.
Our founder, Craig Petronella, holds CMMC-RP, CCNA (Cisco Certified Network Associate), CWNE (Certified Wireless Network Expert), NC Licensed Digital Forensic Examiner license #604180, and an MIT AI certificate. He has 30+ years of experience and founded the company in 2002. This depth of experience ensures that you are working with a team that understands both the technical and regulatory aspects of private AI deployment.
Primary sources for this guide: AI Risk Management Framework.
Related reading
- CMMC Compliance: Gap Assessment, Levels 1 to 3
- How to Build a Private LLM for Business Without a PhD (2026)
- Private AI Inference: Run LLMs On-Prem and Keep Data In-House
- Private AI for CTOs: Why Regulated Teams Leave ChatGPT
- Private LLM Deployment: Run AI Without the Cloud in 2026
Frequently Asked Questions
What is a private AI appliance?
A private AI appliance is a hardware and software system that runs AI models on-premises, keeping your data off the public cloud. It is designed to meet the security and compliance requirements of regulated industries.
How much does a private AI appliance cost?
The cost depends on the hardware and the scale of your deployment. A 7B parameter model runs on a single NVIDIA A100 or H100 GPU. Larger models require 2-4 GPUs. At 500K+ tokens per day, private deployment breaks even within 6-12 months. At 5M+ tokens daily, costs are 60-80% less annually than equivalent API spend.
Can a private AI appliance handle CUI and PHI?
Yes, if it is properly configured. The appliance must be isolated on a segmented VLAN or full air gap. It must use FIPS-validated cryptography for CUI, as required by NIST SP 800-171. It must also meet the security requirements of HIPAA at 45 CFR Part 164 for PHI.
Do I need a PhD to build a private AI system?
No. You do not need a PhD to build a private AI system for business. You need a partner who understands the technology and the regulatory landscape. Petronella Technology Group, Inc. provides turnkey solutions for regulated teams.
What is the difference between a private AI appliance and a cloud AI service?
A private AI appliance runs on your own hardware, giving you full control over your data. A cloud AI service runs on a third-party provider's infrastructure. If you are handling CUI, DFARS 252.204-7012 requires that any cloud service provider meet security requirements equivalent to the FedRAMP Moderate baseline. A private AI appliance avoids this specific cloud provider risk.
How do I get started with a private AI appliance?
The first step is to define your data boundary. Identify which data classes will interact with the model and which regulatory frameworks apply. Then, contact a provider who can help you size the hardware and design the deployment. The first call is a free 30-minute scoping consultation.
If you are ready to move forward, call Penny, our AI assistant, at 919-348-4912, or use our contact form to schedule a consultation. Our team is ready to help you design, build, and operate a private AI appliance that meets your compliance needs.
Reference build sheets, a hardening checklist for open-weight model hosting and a data-sovereignty map for running AI on your own hardware.
Get the free guide