AI Contact Center QA Loops That Cut Hallucinations Fast
Hallucinations in contact centers show up as confident answers that are wrong, outdated, or mismatched to the customer’s situation. They don’t always look dramatic. Sometimes the agent says a policy is “always” one way, or a shipping timeline is “definitely” accurate, or a refund will “automatically” apply. In practice, those details can be slightly off, and the customer pays the price through delays, rework, or repeat calls.
AI can reduce this problem quickly when quality assurance (QA) isn’t a one-time check. The winning pattern is an iterative QA loop that forces the system to verify its outputs against evidence, tighten uncertainty, and route mismatches to the right human action. The goal is speed, but not at the expense of correctness. The loop keeps turning until the answer is safe enough to present, or until it escalates for human handling.
What “hallucination risk” looks like in real customer calls
Not all hallucinations are equal. Some are factual fabrications, others are subtle misinterpretations, and many are failures to align with the actual call context. In a contact center, these issues cluster around a few recurring areas.
- Policy drift: The agent cites a policy that has changed, or references the wrong version for the customer segment.
- Eligibility confusion: The agent states someone qualifies for a refund or waiver when the call details suggest the opposite.
- Order and account mismatch: The agent gives timelines, fees, or steps that apply to a different region, product line, or account type.
- Process misstatements: The agent claims that “the system will do X automatically,” but the workflow actually requires a manual review.
- Tool overreach: The agent answers as if it accessed internal data, even when it did not, or when the retrieved data was stale.
Even when the information is “close,” customers notice gaps in credibility. A small contradiction, like saying a cancellation window is 24 hours when it is 12, can turn a resolved issue into a repeat escalation.
Why one-pass QA fails, even with strong models
A common approach is to generate a response, then run a QA check once, then either accept it or block it. This is better than nothing, but it often misses the key failure mode of generative systems: they can appear correct while skipping the evidence chain. A single pass can also fail to catch partial alignment problems, like tone that sounds reassuring while the factual portion doesn’t match the retrieved policy text.
One-pass QA also has a practical limitation. The QA step often has access to fewer tools and less context than the generation step, so it flags issues late, without enough opportunity to fix them before escalation. When time is tight, the system may choose the safest option available, which is sometimes an unnecessary transfer.
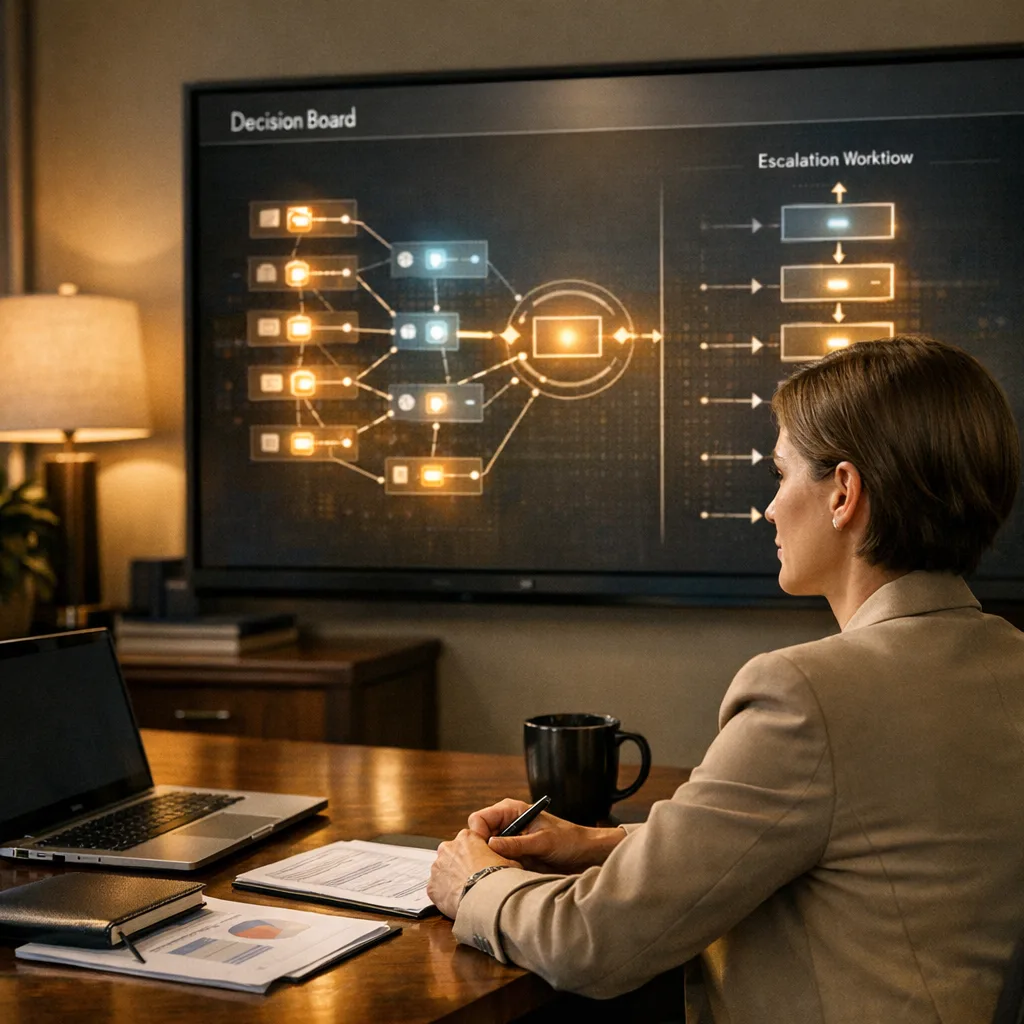
Iterative QA loops solve this by turning verification into a process, not a decision. Instead of “generate, judge, accept or reject,” the loop does “generate, retrieve, verify, revise, re-verify.”
The core loop: generate, evidence-check, uncertainty gate, revise, escalate
An effective AI contact center QA loop usually includes five stages. The details vary by stack, but the logic stays consistent.
- Generate: Produce an agent-ready answer using the conversation transcript, customer attributes, and any available retrieval context.
- Evidence-check: Verify each factual claim against the knowledge base, policy documents, order system facts, or tool outputs. The check focuses on “what must be true” for the answer to be valid.
- Uncertainty gate: If evidence is missing or contradictory, the system reduces certainty, rephrases, or asks clarifying questions. When the risk stays high, it blocks the response.
- Revise: Regenerate only the problematic parts, using the verified evidence and removing claims that lack support.
- Escalate: Route to a human when the system cannot reach a safe answer, or when the customer needs an action the AI cannot perform reliably.
The speed benefit comes from tight scope. Instead of redoing the entire response, the loop targets the claims that failed verification. That approach reduces latency and prevents the model from “drifting” while trying again.
Designing evidence-checks that actually reduce hallucinations
Evidence-checks work best when they are structured around claim verification, not general quality scoring. If the system only outputs a pass or fail, it often lacks the granularity to fix what went wrong. Strong loops attach each factual claim to a verification outcome, then rewrite based on those outcomes.
In practical terms, evidence-checking can include:
- Claim extraction: Break the response into atomic claims, such as “refund is processed within 5 business days” or “cancellation must be within 12 hours.”
- Retrieval alignment: Map each claim to relevant documents, policy sections, or order records.
- Consistency checks: Confirm that the retrieved evidence supports the claim, and that the evidence matches the customer’s region, plan, and product category.
- Temporal checks: Ensure the policy version is current, and that the timeline applies to the order date.
- Actionability checks: Validate that the claimed action is actually possible, and that required steps were included.
A real-world example helps. Suppose a customer calls about a late delivery and asks for compensation. The AI draft says, “Compensation is automatic after 48 hours.” Evidence-checking might find policy text stating compensation is automatic only when certain carriers are involved, and otherwise it requires manual approval. The uncertainty gate then either adjusts the wording, “Depending on carrier and service level, compensation may require review,” or it asks a clarifying question to determine eligibility before committing.
Uncertainty gates, not just confidence labels
Many systems use “confidence” in a vague way, and customers can feel that vagueness as hedging. Uncertainty gating should be operational, not cosmetic. It should decide what to do next, based on which evidence is missing or contradictory.
Examples of uncertainty gates that work in contact centers:
- Missing policy evidence: Ask for a detail that narrows the policy scope, or escalate to a specialist team.
- Contradictory documents: Select the most recent policy version, or present both possibilities with a clear next step, then escalate.
- Missing tool results: Avoid implying the system checked the account. Instead, ask the agent to run the verification step, or route for human access.
- High-impact claims: For refunds, identity verification, or compliance-related statements, block the claim and request human confirmation.
That last item is crucial. High-impact claims include anything that changes money, legal obligations, or safety. The loop should treat these as “evidence required,” not “nice to have.”
Revision strategies that keep the loop fast
When the QA loop says “revise,” many teams accidentally cause a slow, compounding process. The system regenerates everything from scratch, which can introduce new errors. Fast revision focuses on the smallest set of changes needed to pass verification.
Three revision strategies often work well:
- Targeted claim replacement: Replace only the unsupported sentences, leaving the rest intact.
- Evidence-grounded phrasing: Rewrite claims using the exact phrasing from policy documents or tool outputs.
- Constrained templates: Use structured response templates for sensitive categories, like “payment adjustment,” “refund status,” or “warranty coverage.” The template enforces which fields must be verified.
Consider a billing call where the AI mistakenly states a discount “always applies after 30 days.” Evidence-checking finds the discount is contingent on an autopay setting. A targeted revision swaps the sentence for: “This discount depends on your autopay setting, and I can confirm it once we check your account preference.” The response keeps empathy while removing the unsupported certainty.
Human escalation as a safety valve, not a default
Escalation should be part of the loop’s logic, not a last resort. The AI should escalate when it cannot reach a safe answer quickly, but it should not escalate for issues that can be fixed by a clarification or a rephrase.
A useful way to structure escalation is to classify failures into buckets:
- Fixable by retrieval: Evidence exists but wasn’t retrieved. The loop re-runs retrieval with better query terms.
- Fixable by clarification: Missing customer detail prevents eligibility determination. The loop asks one or two precise questions.
- Fixable by tool calls: The AI needs account or order data. The loop triggers the required tool call and then re-checks.
- Not fixable automatically: Compliance, fraud, exceptions, or complex overrides require human judgment. Escalate with the evidence trail.
In many contact centers, the human agent’s workload drops when the escalation includes structured context. Instead of transferring an unclear message, the system sends the failing claim, the relevant policy excerpt it checked, and the exact reason it could not confirm eligibility.
Real-world QA loop walkthrough: refund eligibility
Imagine a customer request: “I want a refund, and the order was cancelled after I returned the item.” The AI draft responds with a policy-based answer, but it doesn’t yet know whether the customer falls under the “return initiated within X days” policy or the “defect replacement” policy.
The loop begins:
- Generate: The AI states the likely refund timeline and says a refund is processed automatically.
- Evidence-check: The claim extraction identifies two high-impact statements: refund eligibility and refund timeline. The check retrieves both “return initiated” and “defect replacement” policies, then sees conflicting eligibility rules.
- Uncertainty gate: The loop marks eligibility as uncertain. It blocks the “automatic processing” claim because the “automatic” clause applies only to one policy path.
- Revise: The AI rewrites the response to avoid committing to a specific refund route. It asks for one missing detail, such as the return initiation date or whether the return was marked as defective.
- Escalate or resolve: If the agent can provide the missing date, the loop re-checks and confirms the correct policy. If not, it escalates with a clear reason.
The customer experience stays coherent. The system doesn’t hide uncertainty in vague language. It converts uncertainty into a precise next step, which also reduces repeat calls.
Real-world QA loop walkthrough: technical support with safe uncertainty
In technical support, hallucinations can cause misconfiguration. A user might ask, “Why is my device stuck on firmware update?” The AI could suggest steps like “reset the router and then reinstall firmware,” but it might cite incorrect firmware versions, wrong recovery steps, or unsupported menus.
A QA loop for technical support can focus on “procedure validity” and “version alignment.” Here’s a plausible flow:
- Generate: The AI proposes steps and references an “Update Assistant” menu.
- Evidence-check: The system extracts claims about firmware version, menu path, and supported recovery options. It verifies against the knowledge base for that device model and software version.
- Uncertainty gate: If the evidence lacks documentation for the user’s exact version, the loop blocks the steps that depend on that menu path.
- Revise: The AI adapts to a documented generic recovery flow and adds an instruction to confirm the device model string before proceeding.
- Escalate: If the recovery flow includes safety-sensitive warnings, or if logs are required, it routes to a specialist.
This approach avoids the worst failure mode, where the AI confidently instructs something that can make matters worse. The loop doesn’t just assess “helpfulness,” it validates whether the steps exist for the user’s context.
Telemetry and QA metrics that reveal hallucination patterns
Quality loops need measurement, but the metrics should track risk reduction, not just conversational fluency. Teams often start by monitoring message-level pass or fail rates, then later discover they missed where hallucinations cluster.
Metrics that commonly correlate with hallucination reduction include:
- Claim verification rate: The share of factual claims that successfully match evidence.
- Unsupported-claim rate: The share of claims rejected by the evidence-check step.
- Revision count per response: Higher revision counts can be a sign of retrieval gaps, but dropping revision counts over time suggests improvement.
- Escalation reason distribution: Tracking whether escalations are mostly “missing info,” “tool unavailable,” or “policy exception” helps tune the loop.
- Human override frequency: How often agents correct AI answers, especially on factual details.
- Recontact rate: Customers who call again shortly after may indicate unresolved uncertainty or misstatements.
One practical tactic is to tag each escalation with the specific claim type. “Refund eligibility uncertainty” behaves differently than “wrong procedure for device recovery.” Those tags help you update retrieval prompts, improve evidence-check mappings, and refine escalation thresholds.
Building retrieval that the QA loop can trust
A QA loop depends on retrieval quality. If the system retrieves irrelevant or outdated documents, the evidence-check will either reject everything or, worse, confirm the wrong thing. That’s why retrieval should be tuned for QA, not only for answer generation.
Common retrieval improvements that support hallucination reduction:
- Version-aware document indexing: Index policy documents with effective dates, product tiers, and region tags.
- Metadata-filtered search: Use structured filters, like plan ID or country, before retrieval.
- Answer-time re-ranking: Re-rank retrieved passages based on claim relevance to the draft response.
- Source passage linking: Store the exact passage IDs so evidence-check can cite or re-verify with high fidelity.
- Tool-result caching: When tool outputs are expensive or slow, cache them for consistent re-checks during the same call.
In many deployments, retrieval errors look like hallucinations to the customer because the AI repeats the wrong information. With a strong QA loop, retrieval issues become visible as “failed evidence-check due to mismatch,” which is easier to fix.
Prompting patterns that encourage verification behavior
The loop often includes prompting or instructions for both generation and verification. The goal is to make the system behave like a careful analyst, not a storyteller.
Good guidance to embed in the generation stage:
- Use retrieval evidence when available, and don’t claim access to data that wasn’t retrieved.
- Convert policies into conditional statements when eligibility depends on missing details.
- Separate facts from recommendations, especially for troubleshooting.
Good guidance to embed in the evidence-check stage:
- Verify each factual claim individually.
- Flag missing evidence explicitly.
- Prefer the most recent policy passage when multiple versions appear.
- Classify failures into fixable-by-retrieval, fixable-by-clarification, or not fixable automatically.
When these instructions are consistent across stages, the loop becomes predictable. That predictability is what lets you tune thresholds for speed without sacrificing safety.
Latency management: keeping the loop responsive
QA loops can add round trips, so latency control matters. A system that verifies everything from scratch might feel slow, which encourages shortcuts and higher risk.
Teams often reduce latency by combining three tactics:
- Short-circuiting: If the evidence-check finds a critical unsupported claim early, skip remaining checks and go straight to revise or escalate.
- Incremental verification: Verify only the parts of the response that contain factual claims, not every conversational sentence.
- Parallel tool calls: If the call involves both account data and policy documents, run retrieval and tool queries in parallel, then check consistency once both results arrive.
Speed targets should match the customer experience. In many cases, a one-question clarification, plus evidence verification, resolves faster than an immediate escalation. The loop is designed to find that middle ground.
Security, compliance, and audit trails inside the loop
Contact centers often operate under strict compliance needs. A QA loop can improve auditability by storing what evidence was used and what claims were rejected.
- Traceable evidence: Keep references to document passage IDs and tool result timestamps.
- Claim rejection logs: Record why a claim failed, such as “no policy match,” “policy version mismatch,” or “eligibility contradictory.”
- Role-based escalation: Route exceptions to the right queue with the evidence trail.
- Data minimization: Avoid including sensitive fields in prompts unless needed for verification.
This structure helps audits and also helps developers improve the system. When hallucinations slip through, the logs reveal whether the failure was retrieval, verification mapping, or revision logic.
Common pitfalls that weaken QA loops
Several issues can undermine an otherwise solid QA loop.
- Over-trusting weak evidence-checks: If the checker is too lenient, it will “verify” claims without real support.
- Claim segmentation errors: If the system fails to extract atomic claims, the evidence-check cannot map failures to specific sentences.
- Revision without constraints: Regenerating broadly increases drift and can reintroduce the same unsupported claim with new wording.
- Escalation without context: Transfers that lack the failing claim and evidence require extra time, and can frustrate customers.
- Ignoring temporal validity: Policies change. Without date-aware retrieval, the loop can confirm outdated information.
A good loop actively resists these pitfalls. It should be strict on high-impact claims, precise on evidence mapping, and disciplined in revisions.
In Closing
AI contact center QA loops work because they treat hallucinations as a solvable engineering problem: generate with evidence-aware constraints, verify claim-by-claim, and revise only within clear boundaries. When the loop is disciplined about missing evidence, policy recency, and latency, it becomes both safer and faster—helping agents resolve issues with fewer back-and-forths and clearer escalation paths. For teams looking to implement or further refine these patterns, Petronella Technology Group (https://petronellatech.com) can be a valuable partner. Take the next step by auditing your current workflow for claim mapping, evidence traceability, and revision controls—then tune the loop to your speed and compliance targets.
Free, practical, and specific to regulated environments. We will email it to you.
No spam. Unsubscribe anytime.